diff --git "a/00-\347\233\256\345\275\225.md" "b/00-\347\233\256\345\275\225.md"
deleted file mode 100644
index d950068..0000000
--- "a/00-\347\233\256\345\275\225.md"
+++ /dev/null
@@ -1,4 +0,0 @@
-# 目录
-
-###01.[使用socket发送HTTP GET请求](01.使用socket发送HTTP GET请求.md)
-###02.[编写自定义Annotation](02.编写自定义Annotation.md)
diff --git "a/00.\345\276\205\350\247\243\345\206\263\351\227\256\351\242\230.md" "b/00.\345\276\205\350\247\243\345\206\263\351\227\256\351\242\230.md"
deleted file mode 100644
index f36ba9b..0000000
--- "a/00.\345\276\205\350\247\243\345\206\263\351\227\256\351\242\230.md"
+++ /dev/null
@@ -1,35 +0,0 @@
-#00.待解决问题
-
-* 如何禁止用户登出之后浏览器的回退功能?
-* log4j的详细配置:参考这里
-* log4j使用数据库
-* 测试的内存数据库
-* jbmp 5
-* Spring web flow
-* Lucens
-* Hadoop
-* aop
-* webservice
-* mybatis
-* spring security
-* nosql
-* ide自动生成equals、hashcode、toString
-* 原型设计工具Axure
-* Java异常
-* 自定义日志级别
-* 如果你的项目或类,很难进行测试,这说明,你的类或项目的结构很有问题!
-* 跨域访问和同源策略
-* 安全测试
-* 性能测试
-* 各种IO模型
-* MongoDB是否可以解决大数据量的检索问题?
-* mysql多账号(安全账号)、索引、试图、优化查询、调优、备份
-* service层能否互相调用【考虑权限、事务、session】?
-* Spring的事务传播机制
-* 测试的类型,以及如何完成测试
-* HTTP 406 错误的原因
-* https协议,在tomcat和apache搭建
-* JNDI
-* JAAS
-* javascript 在线着色工具
-* 在内部类中的属性和外部方法的参数两者从外表上看是同一个东西,但实际上却不是,所以他们两者是可以任意变化的,也就是说在内部类中我对属性的改变并不会影响到外部的形参,而然这从程序员的角度来看这是不可行的,毕竟站在程序的角度来看这两个根本就是同一个,如果内部类该变了,而外部方法的形参却没有改变这是难以理解和不可接受的,所以为了保持参数的一致性,就规定使用final来避免形参的不改变。
diff --git a/CodeStyle/01.ClassWithOnlyPrivateConstructorsShouldBeFinal.md b/CodeStyle/01.ClassWithOnlyPrivateConstructorsShouldBeFinal.md
new file mode 100644
index 0000000..bdc1c38
--- /dev/null
+++ b/CodeStyle/01.ClassWithOnlyPrivateConstructorsShouldBeFinal.md
@@ -0,0 +1,27 @@
+# 01.ClassWithOnlyPrivateConstructorsShouldBeFinal
+
+如果Class只包含私有的构造方法,则Class应该使用final进行修饰,除非构造方法在内部类中被调用了。
+
+例如:
+
+```Java
+public class Foo {
+ private Foo(){
+ // init
+ }
+}
+```
+
+建议改为:
+
+```Java
+public final class Foo {
+ private Foo(){
+ // init
+ }
+}
+```
+
+只包含私有构造方法的类,一般是工具类或者单例类,为了防止被外部实例化,所以需要私有构造方法。虽然私有构造方法能够防止被外部类继承,但是避免不了内部类继承,所以为了杜绝被内部类继承,所以最好在class上加上final关键字。
+
+
diff --git a/CodeStyle/02.DoNotConcatStringInLog.md b/CodeStyle/02.DoNotConcatStringInLog.md
new file mode 100644
index 0000000..13d73a4
--- /dev/null
+++ b/CodeStyle/02.DoNotConcatStringInLog.md
@@ -0,0 +1,37 @@
+# 02.DoNotConcatStringInLog
+
+不要在日志中拼接字符串,例如:
+
+```Java
+import org.slf4j.Logger;
+import org.slf4j.LoggerFactory;
+
+public class Foo {
+ private static final Logger logger = LoggerFactory.getLogger(Foo.class);
+
+ public void method(int num) {
+ logger.debug("num is " + num);
+ }
+}
+```
+
+日志都是有输出级别的,例如在`info`级别下,`debug`日志不会被打印,但是以上代码却执行了字符串拼接操作,导致了不必要的资源浪费。
+
+可以使用占位符的方式代替字符拼接,在Log4j底层实现中,如果日志不被打印,则会忽略所有的参数输入,避免了不必要的资源浪费。
+
+应该改成使用占位符代替字符串拼接:
+
+```Java
+import org.slf4j.Logger;
+import org.slf4j.LoggerFactory;
+
+public class Foo {
+ private static final Logger logger = LoggerFactory.getLogger(Foo.class);
+
+ public void method(int num) {
+ logger.debug("num is {}", num);
+ }
+}
+```
+
+最后,占位符的日志API是sl4j的接口,log4j并没有占位符的API,所以,我们应该针对sl4j接口编程,而不是log4j。
diff --git a/CodeStyle/03.DoNotLetTheThisReferenceEscapeDuringObjectConstruction.md b/CodeStyle/03.DoNotLetTheThisReferenceEscapeDuringObjectConstruction.md
new file mode 100644
index 0000000..390259c
--- /dev/null
+++ b/CodeStyle/03.DoNotLetTheThisReferenceEscapeDuringObjectConstruction.md
@@ -0,0 +1,8 @@
+# 03.Do not let the this reference escape during object construction
+
+
+
+## 参考资料
+
+* https://www.securecoding.cert.org/confluence/display/java/TSM01-J.+Do+not+let+the+this+reference+escape+during+object+construction
+
diff --git a/CodeStyle/04.DoNotUseBackgroundThreadsDuringClassInitialization.md b/CodeStyle/04.DoNotUseBackgroundThreadsDuringClassInitialization.md
new file mode 100644
index 0000000..2b16ccd
--- /dev/null
+++ b/CodeStyle/04.DoNotUseBackgroundThreadsDuringClassInitialization.md
@@ -0,0 +1,6 @@
+# 04.DoNotUseBackgroundThreadsDuringClassInitializtion
+
+## 参考资料
+
+* # [Do not use background threads during class initialization](https://www.securecoding.cert.org/confluence/display/java/TSM02-J.+Do+not+use+background+threads+during+class+initialization)
+
diff --git a/CodeStyle/05.DoNotPublishPartiallyInitializedObjects.md b/CodeStyle/05.DoNotPublishPartiallyInitializedObjects.md
new file mode 100644
index 0000000..62338b0
--- /dev/null
+++ b/CodeStyle/05.DoNotPublishPartiallyInitializedObjects.md
@@ -0,0 +1,9 @@
+# 03.DoNotPublishPartiallyInitializedObjects
+
+
+
+
+## 参考资料
+
+* # https://www.securecoding.cert.org/confluence/display/java/TSM03-J.+Do+not+publish+partially+initialized+objects
+
diff --git a/CodeStyle/06.UseACorrectFormOfTheDoubleCheckedLockingIdiom.md b/CodeStyle/06.UseACorrectFormOfTheDoubleCheckedLockingIdiom.md
new file mode 100644
index 0000000..d65fa48
--- /dev/null
+++ b/CodeStyle/06.UseACorrectFormOfTheDoubleCheckedLockingIdiom.md
@@ -0,0 +1,102 @@
+# 06.UseACorrectFormOfTheDoubleCheckedLockingIdiom
+
+以下代码在SonarLint上会给出`DoubleCheckedLockingShouldNotBeUsed`的缺陷警告。
+
+```Java
+public class Singleton {
+ private static Singleton instance;
+
+ private Singleton() {
+ }
+
+ public static Singleton getInstance() {
+ if (instance == null) { // 第一次读
+ synchronized (Singleton.class) {
+ if (instance == null) {
+ instance = new Singleton(); // 第二次读
+ }
+ }
+ }
+
+ return instance; // 第三次读
+ }
+}
+```
+
+缺陷原因如下:
+
+`第一次读`和`第三次读`无法避免**指令重排序**,导致第三次读仍然有可能返回null值。为了避免重排序,保证`happen-before`顺序,我们可以使用`volatile`修饰Singleton字段。
+
+修改如下:
+
+```Java
+public class Singleton {
+ private static volatile Singleton instance;
+
+ private Singleton() {
+ }
+
+ public static Singleton getInstance() {
+ if (instance == null) {
+ synchronized (Singleton.class) {
+ if (instance == null) {
+ instance = new Singleton();
+ }
+ }
+ }
+
+ return instance;
+ }
+}
+```
+
+从1.7版本开始,JVM对`synchronied`关键字进行了优化,SonarLint的建议是使用
+
+There are multiple ways to fix this. The simplest one is to simply not use double checked locking at all, and synchronize the whole method instead. With early versions of the JVM, synchronizing the whole method was generally advised against for performance reasons. But synchronized performance has improved a lot in newer JVMs, so this is now a preferred solution. If you prefer to avoid using synchronized altogether, you can use an inner static class to hold the reference instead. Inner static classes are guaranteed to load lazily.
+
+Noncompliant Code Example
+
+```Java
+@NotThreadSafe
+public class DoubleCheckedLocking {
+ private static Resource resource;
+
+ public static Resource getInstance() {
+ if (resource == null) {
+ synchronized (DoubleCheckedLocking.class) {
+ if (resource == null)
+ resource = new Resource();
+ }
+ }
+ return resource;
+ }
+
+ static class Resource {
+
+ }
+}
+```
+
+
+Compliant Solution
+
+```Java
+@ThreadSafe
+public class SafeLazyInitialization {
+ private static Resource resource;
+
+ public synchronized static Resource getInstance() {
+ if (resource == null)
+ resource = new Resource();
+ return resource;
+ }
+
+ static class Resource {
+ }
+}
+```
+
+## 参考资料
+
+* http://www.cs.umd.edu/~pugh/java/memoryModel/DoubleCheckedLocking.html
+
diff --git "a/CodeStyle/07.\346\243\200\346\265\213\345\222\214\351\201\277\345\205\215\346\225\264\346\225\260\350\266\212\347\225\214\346\223\215\344\275\234.md" "b/CodeStyle/07.\346\243\200\346\265\213\345\222\214\351\201\277\345\205\215\346\225\264\346\225\260\350\266\212\347\225\214\346\223\215\344\275\234.md"
new file mode 100644
index 0000000..d272b45
--- /dev/null
+++ "b/CodeStyle/07.\346\243\200\346\265\213\345\222\214\351\201\277\345\205\215\346\225\264\346\225\260\350\266\212\347\225\214\346\223\215\344\275\234.md"
@@ -0,0 +1,44 @@
+# 检测和避免数值越界
+
+在数值的**加**、**减**和**乘**过程中,需要注意整数的越界操作。因为JVM并不会抛出异常,所以在一些关键地方需要特别注意数值的越界问题。例如:
+
+```java
+@Test
+public test(){
+ System.out.println(add(Integer.MAX_VALUE, 1)); // 打印 -2147483648
+}
+
+public void add(int left, int right) {
+ return left + right;
+}
+```
+
+所以,当需操作这类问题时,为了避免程序不正常运行,需要对越界进行判断,例如:
+
+```Java
+public void add(int left, int right) {
+ if (right > 0 ? left > Integer.MAX_VALUE - right
+ : left < Integer.MIN_VALUE - right) {
+ throw new ArithmeticException("Integer overflow");
+ }
+ return left + right;
+}
+```
+
+当操作的数值发生越界问题时,则会抛出`ArithmeticException`异常。
+
+从JDK1.8开始,Math添加了若干用于处理这类问题的方法,例如:
+
+> Math.addExact(x, y)
+>
+> Math.subtractExact(x, y)
+>
+> Math.multiplyExact(x, y)
+>
+> Math.incrementExact(num)
+>
+> Math.decrementExact(num)
+
+当发生越界时,这些方法都会抛出`ArithmeticException`异常。
+
+需要注意的是,这些接口都只支持int和long类型参数,因为在Java中浮点类型的计算是不精确的,如果需要对浮点进行精确的四则运算,应该使用`BigDecimal`对象。
\ No newline at end of file
diff --git "a/CodeStyle/08.\344\270\215\350\246\201\345\234\250\346\225\260\345\200\274\344\270\212\346\267\267\347\224\250\346\214\211\344\275\215\346\223\215\344\275\234\345\222\214\347\256\227\346\234\257\346\223\215\344\275\234.md" "b/CodeStyle/08.\344\270\215\350\246\201\345\234\250\346\225\260\345\200\274\344\270\212\346\267\267\347\224\250\346\214\211\344\275\215\346\223\215\344\275\234\345\222\214\347\256\227\346\234\257\346\223\215\344\275\234.md"
new file mode 100644
index 0000000..a1c5165
--- /dev/null
+++ "b/CodeStyle/08.\344\270\215\350\246\201\345\234\250\346\225\260\345\200\274\344\270\212\346\267\267\347\224\250\346\214\211\344\275\215\346\223\215\344\275\234\345\222\214\347\256\227\346\234\257\346\223\215\344\275\234.md"
@@ -0,0 +1,2 @@
+# 不要在数值上混用按位操作和算术操作
+
diff --git "a/CodeStyle/08.\350\277\224\345\233\236\347\251\272\351\233\206\345\220\210\344\273\243\346\233\277NULL.md" "b/CodeStyle/08.\350\277\224\345\233\236\347\251\272\351\233\206\345\220\210\344\273\243\346\233\277NULL.md"
new file mode 100644
index 0000000..c1dded8
--- /dev/null
+++ "b/CodeStyle/08.\350\277\224\345\233\236\347\251\272\351\233\206\345\220\210\344\273\243\346\233\277NULL.md"
@@ -0,0 +1,44 @@
+# 返回空集合代替NULL
+
+ 在编写方法的过程中,如果方法返回集合或者数组,当数据集或数组为空时,尽量统一返回空集合或者空数组。这样可以避免过多的null判断,甚至会抛出NPE异常。
+
+ 不好的写法:
+
+ ```Java
+public static List getResults() {
+ return null; // 不好的写法
+}
+
+public static Result[] getResults() {
+ return null; // 不好的写法
+}
+
+public static void main(String[] args) {
+ Result[] results = getResults();
+
+ if (results != null) { // 这里需要判空,漏掉的话会抛出NPE异常
+ for (Result result: results) {
+ /* ... */
+ }
+ }
+}
+
+ ```
+
+ 推荐写法:
+
+ ```Java
+public static List getResults() {
+ return Collections.emptyList(); // 推荐写法
+}
+
+public static Result[] getResults() {
+ return new Result[0]; // 推荐写法
+}
+
+public static void main(String[] args) {
+ for (Result result: getResults()) { // 直接迭代不需要判null,也不会有NPE的潜在威胁
+ /* ... */
+ }
+}
+ ```
diff --git "a/CodeStyle/09.\345\276\252\347\216\257\346\227\266\344\275\277\347\224\250\350\257\255\344\271\211\345\214\226\347\232\204\350\277\255\344\273\243\345\217\230\351\207\217\345\220\215.md" "b/CodeStyle/09.\345\276\252\347\216\257\346\227\266\344\275\277\347\224\250\350\257\255\344\271\211\345\214\226\347\232\204\350\277\255\344\273\243\345\217\230\351\207\217\345\220\215.md"
new file mode 100644
index 0000000..ad36523
--- /dev/null
+++ "b/CodeStyle/09.\345\276\252\347\216\257\346\227\266\344\275\277\347\224\250\350\257\255\344\271\211\345\214\226\347\232\204\350\277\255\344\273\243\345\217\230\351\207\217\345\220\215.md"
@@ -0,0 +1,29 @@
+# 循环时使用语义化的迭代变量名
+
+很多人在写循环时,经常使用i、j、k这样的变量名,如果是一层循环还好,当出现多循环时,这种命名方式十分不友好,例如:
+
+```Java
+// Nodes[][] nodes = new Nodes[5][5]; nodes是一个5*5的表格
+
+for (int i = 0; i < nodes.length; i++) {
+ for (int j = 0; j < nodes[i].length; j++) {
+ Node node = nodes[i][j];
+ // 其他操作
+ }
+}
+```
+
+推荐写法:
+
+```Java
+// Nodes[][] nodes = new Nodes[5][5]; nodes是一个5*5的表格
+
+for (int row = 0; row < nodes.length; row++) {
+ for (int col = 0; col < nodes[row].length; col++) {
+ Node node = nodes[row][col];
+ // 其他操作
+ }
+}
+```
+
+第二种写法明显要优于第一种写法,当内部循环操作稍微复杂时,这种写法的优势就更加明显了。
diff --git "a/CodeStyle/10.\351\201\277\345\205\215\344\270\242\345\244\261\345\274\202\345\270\270\344\277\241\346\201\257.md" "b/CodeStyle/10.\351\201\277\345\205\215\344\270\242\345\244\261\345\274\202\345\270\270\344\277\241\346\201\257.md"
new file mode 100644
index 0000000..50db89a
--- /dev/null
+++ "b/CodeStyle/10.\351\201\277\345\205\215\344\270\242\345\244\261\345\274\202\345\270\270\344\277\241\346\201\257.md"
@@ -0,0 +1,51 @@
+# 避免丢失异常信息
+
+异常信息对缺陷的查找非常有用,所以我们应该尽量避免丢失异常信息,常见的异常信息丢失有以下几种情况:
+
+## 吞掉异常信息不处理
+
+```Java
+public void method() {
+ try {
+ fileCreate();
+ } catch (FileAlreadyExistsException e) {
+ // 直接吞掉异常不处理
+ }
+}
+```
+
+推荐做法有:
+
+* 如果能处理的话,则日志记录并做对应处理
+
+```Java
+public void method() {
+ try {
+ fileCreate();
+ } catch (FileAlreadyExistsException e) {
+ logger.error('File already exsists, use it instead');
+ // use old file
+ }
+}
+```
+
+* 如果不能处理,则重新抛出异常
+
+> 1 可以将可检异常转化为运行时异常,统一由上层AOP进行处理
+
+> 2 也可以包装成其他更为语义化的异常类
+
+
+但是不管使用哪种方式,上一个异常的信息也不能丢掉,写法如下:
+
+```Java
+public void method() {
+ try {
+ fileCreate();
+ } catch (FileAlreadyExistsException e) {
+ throw new BizException("File exists", e); // 需要注意这里的e,这样可以避免上一个异常栈丢失!
+ }
+}
+```
+
+ `throw new BizException("File exists", e);` 需要注意这里的**e**,这样可以避免上一个异常栈丢失!千万不要写成`throw new BizException("File exists");`这样会导致上一个异常栈丢失,难以对缺陷进行排查。
diff --git "a/CodeStyle/11.\346\257\224\350\276\203\346\227\266\344\274\230\345\205\210\345\260\206\345\255\227\351\235\242\351\207\217\346\224\276\345\211\215\351\235\242.md" "b/CodeStyle/11.\346\257\224\350\276\203\346\227\266\344\274\230\345\205\210\345\260\206\345\255\227\351\235\242\351\207\217\346\224\276\345\211\215\351\235\242.md"
new file mode 100644
index 0000000..eefa877
--- /dev/null
+++ "b/CodeStyle/11.\346\257\224\350\276\203\346\227\266\344\274\230\345\205\210\345\260\206\345\255\227\351\235\242\351\207\217\346\224\276\345\211\215\351\235\242.md"
@@ -0,0 +1,19 @@
+# 比较等操作时优先将字面量放前面
+
+```Java
+public void method(String name){
+ if(name.equals("john")) {
+ // ...
+ }
+}
+```
+
+上面的代码当name为null时会抛NPE异常,所以需要判空,但有更好的写法就是将字面量跟变量调换位置,如下:
+
+```Java
+public void method(String name) {
+ if("john".equals(name)) {
+ // ...
+ }
+}
+```
diff --git a/CodeStyle/README.md b/CodeStyle/README.md
new file mode 100644
index 0000000..aff7d63
--- /dev/null
+++ b/CodeStyle/README.md
@@ -0,0 +1 @@
+# CodeStyle
diff --git "a/Java-Advanced/01.\347\272\277\347\250\213\346\261\240\346\225\260\351\207\217\350\256\276\347\275\256.md" "b/Java-Advanced/01.\347\272\277\347\250\213\346\261\240\346\225\260\351\207\217\350\256\276\347\275\256.md"
new file mode 100644
index 0000000..ca99c4b
--- /dev/null
+++ "b/Java-Advanced/01.\347\272\277\347\250\213\346\261\240\346\225\260\351\207\217\350\256\276\347\275\256.md"
@@ -0,0 +1,74 @@
+# 线程池数量设置
+
+## lscpu 查看CPU信息
+
+```bash
+alvas@server:~$ lscpu
+Architecture: x86_64
+CPU op-mode(s): 32-bit, 64-bit
+Byte Order: Little Endian
+CPU(s): 96
+On-line CPU(s) list: 0-95
+Thread(s) per core: 2
+Core(s) per socket: 12
+Socket(s): 4
+NUMA node(s): 4
+Vendor ID: GenuineIntel
+CPU family: 6
+Model: 62
+Model name: Intel(R) Xeon(R) CPU E5-4657L v2 @ 2.40GHz
+Stepping: 4
+CPU MHz: 2700.000
+CPU max MHz: 2900.0000
+CPU min MHz: 1200.0000
+BogoMIPS: 4801.91
+Virtualization: VT-x
+L1d cache: 32K
+L1i cache: 32K
+L2 cache: 256K
+L3 cache: 30720K
+NUMA node0 CPU(s): 0,4,8,12,16,20,24,28,32,36,40,44,48,52,56,60,64,68,72,76,80,84,88,92
+NUMA node1 CPU(s): 1,5,9,13,17,21,25,29,33,37,41,45,49,53,57,61,65,69,73,77,81,85,89,93
+NUMA node2 CPU(s): 2,6,10,14,18,22,26,30,34,38,42,46,50,54,58,62,66,70,74,78,82,86,90,94
+NUMA node3 CPU(s): 3,7,11,15,19,23,27,31,35,39,43,47,51,55,59,63,67,71,75,79,83,87,91,95
+```
+
+这其中有两个配置比较值得我们关注:
+
+```bash
+CPU(s): 96 // CPU核心数
+Thread(s) per core: 2 // 每个核心支持的超线程数
+```
+
+CPU核心数决定了同一时间计算机所能并行执行的处理单元,也就是说96个CPU核心,就决定了计算机最大的并行数量是96。
+
+每个核心只能同时执行一个线程,而对于核心里的超线程,只是为了减少多个线程切换时的系统开销,并不具有并行的特征。
+
+## IO密集型 VS CPU密集型
+
+### CPU密集型
+
+对于CPU密集型的应用来说,阻塞的操作不存在或者很少,那就要求我们尽可能地利用CPU,但同时减少不必要的线程切换。我们可以将线程数设置为N+1(为什么不是N?)。
+
+N+1这对于单纯仅有CPU操作的应用来说,这是非常合理的。例如,我们要计算海量的计算操作,可以将数量分96份,然后通过96个线程去处理,最后将结果汇总。但是如果我们用双倍的线程192个去处理的话,那么性能反而会下降。因为计算机的最高并行数是96个,这就意味着,CPU还要使用额外的时间片去处理线程间的切换,反而浪费了CPU时间。
+
+而对于有少量IO的操作来说,可以稍微将这个值设置高一些,在一些线程进行IO等待的时候,可以进行线程切换。但是具体的值需要根据情况而定。
+
+### IO密集型
+
+对于IO密集型的操作来说,线程的大部分时间都会处于IO等待,例如网络IO,本地磁盘IO等,由于IO等待时间远远高于线程切换时间,特别是超线程切换时间(IO等待时间 > CPU核心线程切换时间 > 超线程切换时间)。
+
+对于一核一线程的计算机来说,2N+1算是一个合理且简单粗暴的值。
+
+而对于一核M线程(超线程)的计算机来说,2 * N * M也是远远可以接受的。(N是核心数,M是核心支持的超线程数)。
+
+而最接近真理的值,一定要通过平均IO等待时间,平均CPU切换实现,平均超线程切换时间来进行计算。
+
+### 为什么+1
+
+> 对于计算密集型的任务,在拥有N个处理器的系统上,当线程池的大小为N+1时,通常能实现最优的效率。(即使当计算密集型的线程偶尔由于缺失故障或者其他原因而暂停时,这个额外的线程也能确保CPU的时钟周期不会被浪费。)
+
+## 操作资料
+
+* https://ifeve.com/how-to-calculate-threadpool-size/
+
diff --git "a/Java-Advanced/02.Hibernate\344\271\220\350\247\202\351\224\201.md" "b/Java-Advanced/02.Hibernate\344\271\220\350\247\202\351\224\201.md"
new file mode 100644
index 0000000..e30f185
--- /dev/null
+++ "b/Java-Advanced/02.Hibernate\344\271\220\350\247\202\351\224\201.md"
@@ -0,0 +1,116 @@
+# Hibernate乐观锁
+
+Hibernate支持乐观锁的实现,不需要我们手撸Native SQL。主要有两种乐观锁实现:依赖版本号的乐观锁(Optimistic locking),不依赖版本号的乐观锁(Versionless optimistic locking)
+
+不同的乐观锁实现,具有不同的效果,下面我们以货品订阅为例子:
+
+例如下面这个货品订阅的例子:
+
+```Java
+@Entity
+public class Goods {
+ @Column
+ private int id;
+
+ @Column
+ private String name;
+
+ @Column
+ private int count;
+
+ // ...省略setter和getter
+}
+```
+
+Service代码:
+
+```Java
+@Service
+public class GoodsService {
+ @Autowired
+ private GoodsRepository goodsRepository;
+
+ @Transactional
+ public void booking(int id, int count) {
+ Goods goods = goodsRepository.findOne(id);
+ goods.setName("可乐_2");
+ goods.setCount(goods.getCount() - count);
+
+ goodsRepository.save(goods);
+ }
+
+}
+
+```
+
+假如数据记录是:
+
+```json
+{
+ id: 1,
+ name: "可乐_1",
+ count: 1000
+}
+```
+
+我们要减少的库存是100个。
+
+## 依赖版本号的乐观锁
+
+依赖版本号的乐观锁,其实就是在数据库表中添加一个代表版本号的字段,例如version,然后在更新的时候,检测version是否与预期一致,否则抛出`OptimisticLockingException`异常。
+
+依赖版本号的乐观锁实现,需要在Entity中加入带有`@Version`注释的字段(int、long或Date类型),例如
+
+
+```Java
+@Column
+@Version
+private long version;
+```
+
+那么我们在执行`goodsRepository.save(goods)`操作时,对应的SQL代码则是(假设version=111):
+
+```SQL
+begin;
+select * from goods where id1=; // {id:1,name:"可乐_1",count:1000,version:111}
+
+update goods set name="可乐_2", count=900 where version=111;
+// commit或者rollback
+```
+
+在更新goods数据时,会对当前版本跟之前的进行比较,如果版本不匹配,则会抛出`StaleStateException`或`OptimisticLockException`异常。是否进行回滚则需要业务逻辑根据情况而定,一般回滚或进行重试。
+
+## 不依赖版本号的乐观锁
+
+不依赖版本号的乐观锁,就是不使用添加额外的字段,而是采用表原本的字段进行“版本”判断,有两种情况:
+
+* 依赖修改的字段进行判断(OptimisticLockType.DIRTY);
+* 依赖全字段判断(OptimisticLockType.DIRTY)
+
+### 依赖修改的字段
+
+例如上面的Service中修改了name和count字段,则在更新时会依赖与原先的值,SQL语句为:
+
+```SQL
+begin;
+select * from goods where id1=; // {id:1,name:"可乐_1",count:1000,version:111}
+
+update goods set name="可乐_2", count=900 where name='可乐_1' and count = 1000;
+// commit或者rollback
+```
+
+### 依赖全字段
+
+对Entity的所有字段进行判断,如果字段全部匹配则更新,否则抛出异常,SQL语句为:
+
+```SQL
+begin;
+select * from goods where id1=; // {id:1,name:"可乐_1",count:1000,version:111}
+
+update goods set name="可乐_2", count=900 where id=1, name='可乐_1' and count = 1000;
+// commit或者rollback
+```
+
+## 参考资料
+
+* http://docs.jboss.org/hibernate/orm/5.2/userguide/html_single/Hibernate_User_Guide.html#locking
diff --git "a/Java-Advanced/03.TCP\347\232\204\345\215\212\351\230\237\345\210\227\344\270\216\345\205\250\351\230\237\345\210\227.md" "b/Java-Advanced/03.TCP\347\232\204\345\215\212\351\230\237\345\210\227\344\270\216\345\205\250\351\230\237\345\210\227.md"
new file mode 100644
index 0000000..226db31
--- /dev/null
+++ "b/Java-Advanced/03.TCP\347\232\204\345\215\212\351\230\237\345\210\227\344\270\216\345\205\250\351\230\237\345\210\227.md"
@@ -0,0 +1,24 @@
+# TCP的半队列与全队列
+
+在TCP三次握手过程中,被连接端会为维护两个队列,一个是**syns queue**,另外一个是**accept queue**。
+
+### syns queue(半连接队列)
+
+**syns queue**是sever端接收SYN请求时维护的一个队列,用来记录发送了SYN的TCP连接。当客户端发送了ACK之后,就会将数据从这个队列中移除。
+
+著名的**syn floods攻击**就是利用了这个队列的特征,不断发送SYN请求,但不发送ACK,导致**syns queue**溢出的攻击。
+
+### accept queue(全连接队列)
+
+**accept queue**是server端接收ACK请求后维护的一个队列,用来记录已经建立三次握手的TCP连接,但未与服务建立真正连接(server没有accept),当server建立accept之后,就会从这个队列中移除。
+
+
+
+### 查看半队列/全队列大小
+
+Recv-Q Send-Q
+
+### 半队列/全队列月backlog关系
+
+### 最佳实践
+
diff --git a/Java-Advanced/04.Socket-Too many open files.md b/Java-Advanced/04.Socket-Too many open files.md
new file mode 100644
index 0000000..e69de29
diff --git "a/Java-Advanced/05.TCP\347\232\204CLOSE_WAIT\345\222\214TIME_WAIT.md" "b/Java-Advanced/05.TCP\347\232\204CLOSE_WAIT\345\222\214TIME_WAIT.md"
new file mode 100644
index 0000000..4d85f49
--- /dev/null
+++ "b/Java-Advanced/05.TCP\347\232\204CLOSE_WAIT\345\222\214TIME_WAIT.md"
@@ -0,0 +1,35 @@
+# TCP的CLOSE_WAIT和TIME_WAIT
+
+难免会遇到TCP的CLOSE_WAIT和TIME_WAIT过多的情况,了解这个两个状态值对调优具有十分重要的重用。
+
+### 四次挥手
+
+下面是TCP的断开协议(四次挥手)的状态图。需要注意的是,图里所示的断开方为Client,而实际情况下,断开也可以是Server。
+
+
+
+#### FIN_WAIT_1
+
+主动断开方会发送FIN给对端,表示要断开TCP连接,同时自己进入**FIN_WAIT_1**状态。
+
+#### CLOSE_WAIT
+
+被动断开方收到FIN后,回应ACK并进入**CLOSE_WAIT**状态,此时并没有直接发送**FIN&ACK**,主要是因为被动关闭的一方,可能还有数据未发送完,需要时间窗口发送数据,所以进入的是**CLOSE_WAIT**状态,并发送数据(也可能没有数据)。
+
+### LAST_ACK
+
+被动断开方,发送完数据之后,向对端发送**FIN&ACK**表示数据已经发送完毕,可以正式关闭连接,并进入**LAST_ACK**状态,等待最终关闭确认。
+
+#### TIME_WAIT
+
+主动断开方收到**FIN&ACK**之后,确认被动端开方已经发送完数据可以正式关闭。此时,如果主动断开方已经接受完数据包,则可以向对端发送**ACK**,自己进入**TIME_WAIT**状态。此时,被动断开方的所有操作已经完成,只要等待2MSL的超时时间,就可以进入**CLOSED**状态。
+
+#### CLOSE
+
+被动断开方收到最后的**ACK**之后直接进入**CLOSE**状态。需要注意的是,主动断开方需要等待2MSL的时间。
+
+### TIME_WAIT为什么需要等待2MSL
+
+TIME_WAIT需要等待2MSL时间,主要是为了确保双方正常关闭。在主动端开方发送最后一个ACK之后,这个ACK可能会丢失,或者超时,导致被动端开方超时发送**FIN&ACK**,如果此时主动端开方已经进入**CLOSE**状态,则被动端开方会抛出**connect reset**的错误。
+
+还有一个原因就是给足够的时间让数据包在网络中及时传送到目标,避免新的同一个端口同一个对端的连接的数据包混淆。想象一下,如果在断开的AB两端,快速建立TCP连接,此时第二次连接的TCP包可能会先于第一次的数据包到达对端,你让接收方情何以堪?
\ No newline at end of file
diff --git a/Java-Advanced/06.CopyOnWriteArrayList.md b/Java-Advanced/06.CopyOnWriteArrayList.md
new file mode 100644
index 0000000..539998f
--- /dev/null
+++ b/Java-Advanced/06.CopyOnWriteArrayList.md
@@ -0,0 +1,2 @@
+# CopyOnWriteArrayList
+
diff --git "a/Java-Advanced/07.\345\215\225\347\202\271\347\231\273\345\275\225\345\256\236\347\216\260.md" "b/Java-Advanced/07.\345\215\225\347\202\271\347\231\273\345\275\225\345\256\236\347\216\260.md"
new file mode 100644
index 0000000..bc7f2f3
--- /dev/null
+++ "b/Java-Advanced/07.\345\215\225\347\202\271\347\231\273\345\275\225\345\256\236\347\216\260.md"
@@ -0,0 +1,32 @@
+# 单点登录实现
+
+## 共享Cookie和Session
+
+域名限制
+
+## CAS
+
+### 名词
+
+* **CAS Server:** 登陆认证的服务器;
+* **CAS Client:** 需要单点登录的应用/服务器;
+* **Ticket Granting Ticke(TGT类比Session):** 用户登陆CAS Sever之后,CAS Server保存的Cookie对应的用户信息,其实就是Session;
+* **Ticket-granting cookie(TGC类比Cookie):** 用户登陆CAS Server之后,CAS Server发给用户浏览器的Cookie,最主要的是其中SESSIONID。用来证明用户已经登陆过CAS Server;
+* **Service ticket(ST类比Auth2.0中的token):** ST由CAS Server生成,然后传给用户,用户将ST提交给CAS Client,CAS Client再向CAS Server询问此ST是否合法,如果合法则实现登陆流程,否则失败。
+
+### 过程
+
+假设有两个CAS Client,分别为Server-A和Server-B。用户先后浏览Server-A和Server-B,流程如下:
+
+* 用户先访问Server-A,发现没有登陆,则重定向到CAS Server进行登陆,同时带有redirect_url;
+* 用户输出凭证之后,CAS Server认证用户凭证,并生成TGT和TGC,然后根据TGT生成ST,最后把ST附着在redirect_url上;
+* 用户浏览器收到redirect_url之后,向Server-A发起请求(redirect_url指向Server-A的单点登录接口);
+* Server-A收到请求后,获取ST,然后向CAS Server请求;
+* CAS-Server验证ST,成功之后 CAS Server 返回对应的用户信息;
+* Server-A获取成功验证的信息,生成对应的登录Session信息,表明用户已经登录,然后展示登陆后的内容给用户;
+
+此后,用户访问Server-B服务器,流程如下:
+
+* 用户从Server-A页面跳转到Server-B页面,由于用户在Server-B没有登陆,所以Server-B将用户从定向到CAS Server,并记录当前的url,例如url=server-b-page.html;
+* CAS Server发现用户已经登录(根据TGC判断),则生成新的ST重定向给Server-B;
+* Server-B向CAS Server验证ST并获取用户信息,生成Sesion,然后将用户重定向到url指定的页面;
\ No newline at end of file
diff --git "a/Java-Advanced/08.\345\215\225\347\202\271\347\231\273\345\275\225\345\222\214\350\256\244\350\257\201\346\216\210\346\235\203\347\232\204\345\214\272\345\210\253.md" "b/Java-Advanced/08.\345\215\225\347\202\271\347\231\273\345\275\225\345\222\214\350\256\244\350\257\201\346\216\210\346\235\203\347\232\204\345\214\272\345\210\253.md"
new file mode 100644
index 0000000..da7e8b3
--- /dev/null
+++ "b/Java-Advanced/08.\345\215\225\347\202\271\347\231\273\345\275\225\345\222\214\350\256\244\350\257\201\346\216\210\346\235\203\347\232\204\345\214\272\345\210\253.md"
@@ -0,0 +1,2 @@
+# SSO之CAS
+
diff --git "a/Java-Advanced/09.Java\347\272\277\347\250\213\347\224\237\345\221\275\345\221\250\346\234\237.md" "b/Java-Advanced/09.Java\347\272\277\347\250\213\347\224\237\345\221\275\345\221\250\346\234\237.md"
new file mode 100644
index 0000000..a9da765
--- /dev/null
+++ "b/Java-Advanced/09.Java\347\272\277\347\250\213\347\224\237\345\221\275\345\221\250\346\234\237.md"
@@ -0,0 +1,40 @@
+# Java线程生命周期
+
+Thread.State里规定了Java线程的6个线程状态,分别为:
+
+* Thread.State.NEW
+* Thread.State.RUNNABLE
+* Thread.State.BLOCKED
+* Thread.State.WAITING
+* Thread.State.TIMED_WAITING
+* Thread.State.BLOCKED
+
+> 需要注意是是,Java线程中没有Running状态。不同的编程语言对线程的操作粒度不一样,规定的线程状态也不一样。例如C#=就高达10种线程状态,分别为:Aborted、AbortRequested、Background、Running、Stopped、StopRequested、Suspended、SuspendRequested、Unstarted和WaitSleepJoin。
+
+Java线程不同状态之间的转换如下:
+
+
+
+
+
+## Java线程状态
+
+- **New**:创建了线程对象,但还没调用`start()`方法之前的状态;
+- **Runnable**:当`NEW`状态的线程调用`start()`方法后进入`Runnable`状态;
+ - 线程进入`Runnable`状态不代表会被cpu立即执行,处于该状态的线程需要等待系统调度执行`run()`方法才真正处于运行时,但注意的是Java线程里并没有`Running`状态;
+- **Blocked**:当线程需要等待锁释放时就会进入`Blocked`状态;
+- **Waiting**:当线程需要让自己等待进一步信号( go-ahead signal)来继续执行时,就会进入`Waiting`状态;有以下三种场景:
+ - **线程调用`Object.wait()`进入`Waiting`状态**,其他的线程可以通过`Object.notify()`或`Object.notifyAll()`方法来唤醒处于`Waiting`状态的线程;
+ - **当线程通过调用其他线程的`Thread.join()`方法时,自己本身会进入`Waiting`状态**:当join的线程执行完任务之后,会发送唤醒信号;
+ - **Thread waiting due to LockSupport.park()method being invoked on it:** The waiting thread resumes when `LockSupport.unPark()` is called with the parked thread object as the parameter.
+- **Timed_Waiting**:当线程收到特殊的指示让线程进入特定时间的等待状态时,线程会进入`Timed_Waiting`状态;有以下几种情况会进入`Timed_Waiting`状态:
+ - 调用`Thread.sleep()`方法;
+ - Threads being asked to wait for a permit for a specified amount of time using `LockSuport.parkNanos()` and `LockSupport.parkUntil()` methods.
+ - 调用`Object.wait(long millis)`或`Thread.join(long millis, int manos)`方法;
+- **Terminated**:当线程执行完`run()`方法后就会进入`Terminated`状态;
+
+## 参考资料
+
+* https://www.javabrahman.com/corejava/understanding-thread-life-cycle-thread-states-in-java-tutorial-with-examples/
+* https://www.quora.com/What-is-the-lifecycle-of-thread-in-Java
+* https://msdn.microsoft.com/en-us/library/system.threading.threadstate(v=vs.110).aspx
\ No newline at end of file
diff --git "a/Java-Advanced/10.Java\346\263\233\345\236\213\345\222\214C#\346\263\233\345\236\213\347\232\204\345\214\272\345\210\253.md" "b/Java-Advanced/10.Java\346\263\233\345\236\213\345\222\214C#\346\263\233\345\236\213\347\232\204\345\214\272\345\210\253.md"
new file mode 100644
index 0000000..17338fb
--- /dev/null
+++ "b/Java-Advanced/10.Java\346\263\233\345\236\213\345\222\214C#\346\263\233\345\236\213\347\232\204\345\214\272\345\210\253.md"
@@ -0,0 +1,10 @@
+# Java泛型和C#泛型的区别
+
+## Java泛型
+
+### 类泛型
+
+### 方法方法
+
+## C#泛型
+
diff --git a/Java-Advanced/11.QueryDSL.md b/Java-Advanced/11.QueryDSL.md
new file mode 100644
index 0000000..7bb7670
--- /dev/null
+++ b/Java-Advanced/11.QueryDSL.md
@@ -0,0 +1,2 @@
+# QueryDSL
+
diff --git a/Java-Advanced/12.Model-Entity-DTO-VO-JO-BO.md b/Java-Advanced/12.Model-Entity-DTO-VO-JO-BO.md
new file mode 100644
index 0000000..7bd1e45
--- /dev/null
+++ b/Java-Advanced/12.Model-Entity-DTO-VO-JO-BO.md
@@ -0,0 +1,2 @@
+# Model-Entity-DTO-VO-JO-BO
+
diff --git "a/Java-Advanced/13.\344\270\200\344\272\233\345\270\270\350\247\201\347\232\204\351\235\242\350\257\225\351\242\230.md" "b/Java-Advanced/13.\344\270\200\344\272\233\345\270\270\350\247\201\347\232\204\351\235\242\350\257\225\351\242\230.md"
new file mode 100644
index 0000000..1cbf8ff
--- /dev/null
+++ "b/Java-Advanced/13.\344\270\200\344\272\233\345\270\270\350\247\201\347\232\204\351\235\242\350\257\225\351\242\230.md"
@@ -0,0 +1,34 @@
+
+
+### 什么情况下会发生栈内存溢出?
+
+* 调用栈超过限制;
+* 栈空间无法分配内存;
+
+### Class.forName和ClassLoader.loadClass的区别?
+
+* ClassForName使用默认ClassLoader,而ClassLoder可以指定具体的ClassLoader;
+* ClassForName依赖于类的初始化,而ClassLoader则不;
+
+### Lock与Synchronized 的区别
+
+* Synchronized:
+ * JVM级别的锁,不需要程序员处理释放;
+ * 可重入;
+* Lock
+ * 语言级别的锁;
+ * 需要程序员自己处理释放;
+ * 可分读写锁、公平锁、可重入、可判断、可try,粒度更可控,但也容易出问题;
+
+### sleep和wait的区别?
+
+* sleep是Thead的方法,`Thread.sleep(long millis)`让当前进入休眠,不涉及锁,线程进入`Timed_Waiting`状态;
+
+* wait的Object的方法,`Object.wait()`方法必须在同步块内被调用,调用后,获得对象锁的线程会释放锁,并进入`Timed_Waiting`或`Waiting`状态,需要等待超时唤醒或者被notify/notifyAll唤醒;
+
+### 什么是多态
+
+在面向对象编程中,子类可以实现接口方法,继承父类,重写或者覆盖父类方法。子类可以将引用赋值给父类定义的声明,方法在真正调用过程中,会通过分析调用派生类的方法。
+
+同一操作作用于不同的对象,可以有不同的解释,产生不同的执行结果。在运行时,可以通过指向基类的指针,来调用实现派生类中的方法。
+
diff --git "a/Java-Advanced/14.\344\270\200\350\207\264\346\200\247\345\223\210\345\270\214\347\256\227\346\263\225.md" "b/Java-Advanced/14.\344\270\200\350\207\264\346\200\247\345\223\210\345\270\214\347\256\227\346\263\225.md"
new file mode 100644
index 0000000..f5d08b5
--- /dev/null
+++ "b/Java-Advanced/14.\344\270\200\350\207\264\346\200\247\345\223\210\345\270\214\347\256\227\346\263\225.md"
@@ -0,0 +1,5 @@
+# 一致性哈希算法
+
+## 参考资料
+
+* http://coderroc.com/article/%E7%9F%A5%E8%AF%86%E8%AE%B0%E5%BD%95/Consistent-Hashing.html
\ No newline at end of file
diff --git "a/Java-Advanced/15.\347\274\223\345\255\230\344\270\200\350\207\264\346\200\247.md" "b/Java-Advanced/15.\347\274\223\345\255\230\344\270\200\350\207\264\346\200\247.md"
new file mode 100644
index 0000000..79472fa
--- /dev/null
+++ "b/Java-Advanced/15.\347\274\223\345\255\230\344\270\200\350\207\264\346\200\247.md"
@@ -0,0 +1,2 @@
+# 缓存一致性
+
diff --git "a/Java-Advanced/16.Java\347\272\277\347\250\213\344\270\255\346\226\255\346\234\272\345\210\266.md" "b/Java-Advanced/16.Java\347\272\277\347\250\213\344\270\255\346\226\255\346\234\272\345\210\266.md"
new file mode 100644
index 0000000..02c90f0
--- /dev/null
+++ "b/Java-Advanced/16.Java\347\272\277\347\250\213\344\270\255\346\226\255\346\234\272\345\210\266.md"
@@ -0,0 +1,2 @@
+# Java线程中断机制
+
diff --git "a/Java-Advanced/17.\344\270\200\350\207\264\346\200\247\346\250\241\345\236\213.md" "b/Java-Advanced/17.\344\270\200\350\207\264\346\200\247\346\250\241\345\236\213.md"
new file mode 100644
index 0000000..8195f98
--- /dev/null
+++ "b/Java-Advanced/17.\344\270\200\350\207\264\346\200\247\346\250\241\345\236\213.md"
@@ -0,0 +1,32 @@
+# 一致性模型
+
+## 以数据为中心的一致性模型
+
+### 严格一致性(Strict consistency )
+
+严格一致性模型也被称为原子一致性模型。它是最严格的同步模型,也是最理想化的一致性模型,因为通信总会存在延迟,所以它也是几乎是不可能被实现的一致性模型。最接近严格一致性的做法,就是将系统运行在单个机器中并且只有一份内存,以此同时,数据的写操作都需要阻塞所有的读写操作。因为需要非常强的同步条件,所以我们必须牺牲系统的可用性和容错性,在很多情况下,这机会是不可能被接受的。
+
+### 顺序一致性
+
+
+
+### 因果一致性
+
+### 入口一致性
+
+## 以客户为中心的一致性模型
+
+### 单调读一致性
+
+### 单调写一致性
+
+### 读写一致性
+
+### 写读一致性
+
+## 参考资料
+
+* https://en.wikipedia.org/wiki/Consistency_model
+* 《Consistency models in modern distributed systems. Anapproach to EventualConsistency》
+* 《Distributed Systems: Concurrency and Consistency》
+* https://books.google.com/books?hl=zh-CN&lr=&id=8ksgDgAAQBAJ&oi=fnd&pg=PP1&dq=Distributed+Systems:+Concurrency+and+Consistency&ots=D-y1fFw4Yo&sig=UCOUqfOK5Ks9FSQv7xnHyUDXT5o#v=onepage&q=Distributed%20Systems%3A%20Concurrency%20and%20Consistency&f=false
\ No newline at end of file
diff --git "a/Java-Advanced/19.Spring\344\272\213\345\212\241\347\256\241\347\220\206\351\234\200\350\246\201\346\263\250\346\204\217\347\232\204\351\227\256\351\242\230.md" "b/Java-Advanced/19.Spring\344\272\213\345\212\241\347\256\241\347\220\206\351\234\200\350\246\201\346\263\250\346\204\217\347\232\204\351\227\256\351\242\230.md"
new file mode 100644
index 0000000..d774815
--- /dev/null
+++ "b/Java-Advanced/19.Spring\344\272\213\345\212\241\347\256\241\347\220\206\351\234\200\350\246\201\346\263\250\346\204\217\347\232\204\351\227\256\351\242\230.md"
@@ -0,0 +1,52 @@
+# Spring事务管理需要注意的问题
+
+### 方法可见性和@Transactional
+
+当使用默认代理模式(也就是Java动态代理)时,@Transactional只能代理public可行级别的方法,这意味这protected、private或packaga可见性级别的方法都是没有事务代理的,同时也不会抛出任何错误。
+
+如果你需要代理protected、private和package可见性级别的方法,让他们加上事务,则需要使用基于字节码织入的代理方式,该方式是基于类的代理模式,只要将**proxy-target-class**设置为**true**即可。
+
+### 对象内自我调用的事务传播
+
+例如,在一个带有事务的方法A内部调用当前类的带有事务的方法B:
+
+```Java
+@Service
+public class Servier {
+
+ @Transactional
+ public void methodA(){
+ // do something
+ this.methodB();
+ }
+
+ @Transactional(propagation=Propagation.REQUIRES_NEW)
+ public void methodB(){
+ // do something
+ }
+
+}
+```
+
+上面的代码在不同的代理模式下,行为是不一致的,这个需要特别地注意。
+
+#### 基于Java动态代理实现的事务管理
+
+在基于Java动态代理模式下的事务管理,虽然`methodB()`有`@Transactional(propagation=Propagation.REQUIRES_NEW)`注释同时也是`public`方法,但是由于是`methodA()`的内部调用,Java动态代理是没有办法为`methodB()`添加事务的,也就是说,在`methodA()`内部调用的`methodB()`,基于Java动态代理的事务管理是没有办法为`methodB()`添加事务的。可见,在基于Java动态代理模式下的事务管理,只有通过外部调用的方法,才会被添加事务。
+
+在基于Java动态代理实现的事务管理,如果要在内部调用方法里添加事务,可以通过`AopContext`获得当前bean,然后通过**模拟**外部调用来实现事务。代码如下:
+
+```Java
+@Transactional
+public void methodA(){
+ ((Service) AopContext.currentProxy()).methodB();
+}
+```
+
+#### 基于AspectJ代码织入实现的事务管理
+
+基于AspectJ代码织入实现的事务管理,是通过编译期(source-weaving)或者运行期(bytecode-weaving)进行代码织入方式实现的代理方式,而且是基于类进行代理(Java动态代理是基于接口进行代理),同时不受方法级别的影响。
+
+因此上面的方法内部调用的事务方法,在AspetJ模式下,事务传播是可以正常运行的。
+
+在使用Spring Boot时使用AspjectJ,设置**spring.aop.proxy-target-class=true**即可。
diff --git "a/Java-Advanced/20.Spring-Cloud\345\270\270\347\224\250\347\273\204\344\273\266.md" "b/Java-Advanced/20.Spring-Cloud\345\270\270\347\224\250\347\273\204\344\273\266.md"
new file mode 100644
index 0000000..6133efb
--- /dev/null
+++ "b/Java-Advanced/20.Spring-Cloud\345\270\270\347\224\250\347\273\204\344\273\266.md"
@@ -0,0 +1,11 @@
+# Spring Cloud常用组件
+
+* Feign:REST服务调用
+* Hystrix:延时和故障容错
+* Eureka:服务发现
+* Ribbon:负载均衡
+* Turbine:
+* Zuul:
+* ZooKeeper:
+* Kafka:
+
diff --git "a/Java-Advanced/21.Netty\347\272\277\347\250\213\346\250\241\345\236\213.md" "b/Java-Advanced/21.Netty\347\272\277\347\250\213\346\250\241\345\236\213.md"
new file mode 100644
index 0000000..8978442
--- /dev/null
+++ "b/Java-Advanced/21.Netty\347\272\277\347\250\213\346\250\241\345\236\213.md"
@@ -0,0 +1,2 @@
+# Netty线程模型
+
diff --git "a/Java-Advanced/22.Linux\345\206\205\346\240\270TCP\345\217\202\346\225\260\350\260\203\344\274\230.md" "b/Java-Advanced/22.Linux\345\206\205\346\240\270TCP\345\217\202\346\225\260\350\260\203\344\274\230.md"
new file mode 100644
index 0000000..5d811b2
--- /dev/null
+++ "b/Java-Advanced/22.Linux\345\206\205\346\240\270TCP\345\217\202\346\225\260\350\260\203\344\274\230.md"
@@ -0,0 +1,31 @@
+# TCP参数优化
+
+**TCP连接和断开示意图:**
+
+
+
+### backlog
+
+
+
+### nodelay
+
+
+
+### tcp_tw_reus: boolean
+
+默认值是0
+
+该参数用与配置是否快速回收处于**TIME_WAIT**状态的socket。
+
+在默认情况下,TIME_WAIT状态会等待2ML市场来
+
+该文件表示是否允许重新应用处于TIME-WAIT状态的socket用于新的TCP连接(这个对快速重启动某些服务,而启动后提示端口已经被使用的情形非常有帮助)
+
+
+
+## 参考资料
+
+* http://intronetworks.cs.luc.edu/current/html/
+* http://intronetworks.cs.luc.edu/1/html/tcp.html
+* http://blog.csdn.net/bytxl/article/details/46437363
\ No newline at end of file
diff --git a/Java-Advanced/24.CI&CD.md b/Java-Advanced/24.CI&CD.md
new file mode 100644
index 0000000..cdee192
--- /dev/null
+++ b/Java-Advanced/24.CI&CD.md
@@ -0,0 +1,5 @@
+# 持续集成、持续交付/持续部署
+
+* httpwww.ruanyifeng.comblog201509continuous-integration.htm
+
+
\ No newline at end of file
diff --git "a/Java-Advanced/25.\343\200\212Netty\345\256\236\346\210\230\343\200\213\346\200\235\347\273\264\345\257\274\345\233\276.mmap" "b/Java-Advanced/25.\343\200\212Netty\345\256\236\346\210\230\343\200\213\346\200\235\347\273\264\345\257\274\345\233\276.mmap"
new file mode 100644
index 0000000..b7ba9ce
Binary files /dev/null and "b/Java-Advanced/25.\343\200\212Netty\345\256\236\346\210\230\343\200\213\346\200\235\347\273\264\345\257\274\345\233\276.mmap" differ
diff --git "a/Java-Advanced/26.\343\200\212Clean Architecture\343\200\213\346\200\235\347\273\264\345\257\274\345\233\276.mmap" "b/Java-Advanced/26.\343\200\212Clean Architecture\343\200\213\346\200\235\347\273\264\345\257\274\345\233\276.mmap"
new file mode 100644
index 0000000..452b82b
Binary files /dev/null and "b/Java-Advanced/26.\343\200\212Clean Architecture\343\200\213\346\200\235\347\273\264\345\257\274\345\233\276.mmap" differ
diff --git "a/Java-Advanced/27.\345\210\206\345\270\203\345\274\217\346\225\260\346\215\256\344\270\200\350\207\264\346\200\247.md" "b/Java-Advanced/27.\345\210\206\345\270\203\345\274\217\346\225\260\346\215\256\344\270\200\350\207\264\346\200\247.md"
new file mode 100644
index 0000000..fd92984
--- /dev/null
+++ "b/Java-Advanced/27.\345\210\206\345\270\203\345\274\217\346\225\260\346\215\256\344\270\200\350\207\264\346\200\247.md"
@@ -0,0 +1,8 @@
+# 分布式数据一致性
+
+## 参考资料
+
+* [如何保障微服务架构下的数据一致性?](https://mp.weixin.qq.com/s?__biz=MjM5MDE0Mjc4MA==&mid=2650998073&idx=1&sn=76ec151126bd74a4598350908f00333a&chksm=bdbefd6a8ac9747c16b74bdd1b21630b4a7e89e9da60e0fc5d8c177395486aa2ef6b7b3250c4&mpshare=1&scene=23&srcid=09295ddZ8v0FclpmWV4rkne8#rd)
+* [分布式系统一致性保障方案总结](https://mp.weixin.qq.com/s?__biz=MzIyNjE4NjI2Nw==&mid=2652559545&idx=1&sn=19d8b1bae015851c55abc0e55e0c21a8&chksm=f39a3dcdc4edb4dbff571cb5fcc0998e739b82a8df28ea0543478cefd2b154086341313e9ecf&mpshare=1&scene=23&srcid=0929gwbStkLM6p3TSmfEhM8E#rd)
+* [分布式事务的典型处理方式:2PC、TCC、异步确保和最大努力型](http://kaimingwan.com/post/fen-bu-shi/fen-bu-shi-shi-wu-de-dian-xing-chu-li-fang-shi-2pc-tcc-yi-bu-que-bao-he-zui-da-nu-li-xing)
+
diff --git "a/Java-Advanced/28.HashMap\345\222\214HashTable\345\222\214ConcurrentHashMap.md" "b/Java-Advanced/28.HashMap\345\222\214HashTable\345\222\214ConcurrentHashMap.md"
new file mode 100644
index 0000000..1abe79f
--- /dev/null
+++ "b/Java-Advanced/28.HashMap\345\222\214HashTable\345\222\214ConcurrentHashMap.md"
@@ -0,0 +1,12 @@
+# HashMap和HashTable和ConcurrentHashMap
+
+众所周知HashMap是线程不安全的,因此有了HashTable,但HashTable实现线程安全的方法仅仅只是在方法级别上加了`synchronized`关键字,性能低下,原因如下:
+
+* 读写不分离,两者互斥,对于高并发读的场景堪忧;
+* rehash时,同步等待时间过长,时间跟容量大小正相关;
+
+因此,ConcurrentHashMap应运而生,那它是怎么实现线程安全的同时兼备读写的高性能呢?原因有下:
+
+* 对HashMap进行分段处理,相当于两层的HashMap,分别是Segments[]和HashEntry[],将同步隔离在Segment或HashEntry处理;
+* 读写分离,`get()`除了特殊情况,基本不加锁;
+* LinkedList在容量超过阀值的情况下,会改成红黑树,优化了查询效率;
diff --git "a/Java-Advanced/29.Java\351\207\214\345\220\204\347\247\215\344\271\261\344\270\203\345\205\253\347\263\237\347\232\204\351\224\201\346\246\202\345\277\265\345\217\212\345\256\236\347\216\260.md" "b/Java-Advanced/29.Java\351\207\214\345\220\204\347\247\215\344\271\261\344\270\203\345\205\253\347\263\237\347\232\204\351\224\201\346\246\202\345\277\265\345\217\212\345\256\236\347\216\260.md"
new file mode 100644
index 0000000..00b1f10
--- /dev/null
+++ "b/Java-Advanced/29.Java\351\207\214\345\220\204\347\247\215\344\271\261\344\270\203\345\205\253\347\263\237\347\232\204\351\224\201\346\246\202\345\277\265\345\217\212\345\256\236\347\216\260.md"
@@ -0,0 +1,198 @@
+# Java里各种乱七八糟的锁概念及实现
+
+### 重量级锁
+
+### 轻量级锁
+
+### 自旋锁(Spin Lock)
+
+自旋锁是一种非阻塞锁。线程获取锁时,如果锁已经被其他线程占有时,并不会挂起,而是使用循环不停地判断锁的状态,直至获得锁。
+
+Java里的自旋锁是采用CAS来实现的,CPU保证了CAS的原子性。伪代码如下:
+
+```Java
+public class SpinLock {
+ private final AtomicReference lock = new AtomicReference<>(null);
+
+ public void lock() {
+ Thread thread = Thread.currentThread();
+ while(true) {
+ if (lock.compareAndSet(nul, thread)) break;
+ if (lock.get() == thread) break; // 支持可重入
+ }
+ }
+
+ public void unlock() {
+ Thread current = Thread.currentThread();
+ lock.compareAndSet(current, null);
+ }
+}
+```
+
+自旋锁适用于多核CPU下,资源竞争少,预计线程等待锁少于线程上下文切换时间的情况。
+
+### 互斥量/阻塞锁(Mutex)
+
+互斥量是阻塞锁,当线程无法获取锁时被挂起(wait),当其他线程释放锁(互斥量)后,操作系统会唤醒(notify)等待锁的线程,让其进行竞争去获得锁。
+
+`synchronized`、`ReentrantLock`、`LockSupport `、`Object.notify()`、`Object.wait()`等设计到线程挂起唤醒的都是互斥锁的实现。
+
+阻塞锁适用于单核或者CPU核心数很少或资源竞争大,上下文切换时间相对较少的情况。
+
+### 锁升级/降级
+
+* 锁升级:偏向锁->轻量级锁(自旋锁)->重量级锁
+* 锁降级:重量级锁->轻量级锁(自旋锁)->偏向锁
+
+### 锁消除(Lock Elision)
+
+锁消除是JIT的一种优化策略。当JIT通过逃逸技术分析发现同步块里面的代码并没有共享变量,不存在线程安全问题时,就会将同步代码块的锁去掉,以达到优化性能的目的。
+
+### 偏向锁
+
+偏向锁的出现基于这样一种情况:大多数情况锁不仅不存在多线程竞争,而且总是由同一线程线程多次获得。在这种情况下,为了消除线程锁重入的开销,而引入的一种优化机制。
+
+偏向锁的获取与撤销:
+
+> **偏向锁的获取**: 线程获取锁时,先测试对象头里偏向锁指向的线程ID是否为当前线程,如果测试成功则获得锁,如果测试失败,则判断继续判断对象头里偏向锁标识是否为1,如果是则表示当前是偏向锁,则使用CAS将对象头的偏向锁指向当前线程,否则使用CAS竞争锁。
+>
+> **偏向锁的获取**: 略!
+
+### 公平锁/非公平锁(饥渴模式/公平模式)
+
+在Java中,由于`Object.wait()`和`Object.notify()`的实现机制,并不能保证先挂起的线程能够先获得锁。同时由于线程的存在优先级,优先级别高的线程优先获得锁。因此,在默认情况下,Java中的Lock都是非公平锁。
+
+但是可以通过Lock的构造方法来支持公平锁,例如 `new ReentrantReadWriteLock(true)`。
+
+公平锁的实现机制是通过Lock内部维持一个等待唤醒队列来实现的,实现机制如下:
+
+```Java
+public class FairLock {
+ private boolean isLocked = false;
+ private Thread lockingThread = null;
+ private List waitingThreads = new ArrayList();
+
+ public void lock() throws InterruptedException{
+ QueueObject queueObject = new QueueObject();
+ boolean isLockedForThisThread = true;
+ synchronized(this){
+ waitingThreads.add(queueObject);
+ }
+
+ while(isLockedForThisThread){
+ synchronized(this){
+ isLockedForThisThread = isLocked || waitingThreads.get(0) != queueObject;
+ if(!isLockedForThisThread){
+ isLocked = true;
+ waitingThreads.remove(queueObject);
+ lockingThread = Thread.currentThread();
+ return;
+ }
+ }
+ try{
+ queueObject.doWait();
+ }catch(InterruptedException e){
+ synchronized(this) { waitingThreads.remove(queueObject); }
+ throw e;
+ }
+ }
+ }
+
+ public synchronized void unlock(){
+ if(this.lockingThread != Thread.currentThread()){
+ throw new IllegalMonitorStateException("Calling thread has not locked this lock");
+ }
+ isLocked = false;
+ lockingThread = null;
+ if(waitingThreads.size() > 0){
+ waitingThreads.get(0).doNotify();
+ }
+ }
+}
+public class QueueObject {
+ private boolean isNotified = false;
+
+ public synchronized void doWait() throws InterruptedException {
+ while(!isNotified){
+ this.wait();
+ }
+ this.isNotified = false;
+ }
+
+ public synchronized void doNotify() {
+ this.isNotified = true;
+ this.notify();
+ }
+
+ public boolean equals(Object o) {
+ return this == o;
+ }
+}
+```
+
+### 读写锁(ReadWriteLock)
+
+读写锁可以提高读写并发效率。由于写会改变对象状态,而读不会。因此,在没有写操作并发情况下,读操作是可以多线程并行的,当有写操作时,则需要阻塞所有的读操作。Java有`ReadWriteLock`实现,用例如下:
+
+```Java
+ReadWriteLock readWriteLock = new ReentrantReadWriteLock();
+
+public void read() {
+ readWriteLock.readLock().lock();
+ // 如果没有写锁操作,则多个读锁可以进入该临界区;如果存在写锁操作,则不能进入该临界区
+ readWriteLock.readLock().unlock();
+}
+
+public void write() {
+ readWriteLock.writeLock().lock();
+ // 只有获得写锁的进程才能进入该临界区
+ readWriteLock.writeLock().unlock();
+}
+```
+
+`ReentrantReadWriteLock`是读写锁,同时也是支持可重入的读写锁,而`ReadWriteLock`这是个接口。
+
+### 可重入锁(ReentrantLock)
+
+可重入锁的作用就是支持同一个线程依次多次获得/释放同一把锁,从而避免了死锁的发生。操作可重入锁时,如果当前线程已经获得锁,再次请求锁时,可重入锁会判断当前线程跟持有当前锁的线程是否为同一个,如果是则快速获得锁。
+
+同样地,线程释放(`unlock()`)可重入锁时,由于可重入锁内部统计了当前线程获得锁的次数,当获得的次数大于释放次数时,当前线程依然继续持有锁,否则真正释放锁并唤醒其他线程进行锁竞争。
+
+Java中ReentrantLock的用法:
+
+```Java
+class X {
+ private final ReentrantLock lock = new ReentrantLock();
+
+ public void method() {
+ lock.lock();
+ try {
+ } finally {
+ lock.unlock()
+ }
+ }
+ }
+```
+
+### 锁粗化
+
+### 锁膨胀
+
+### 乐观锁
+
+### 悲观锁
+
+
+## 参考资料
+
+* https://docs.oracle.com/cd/E13150_01/jrockit_jvm/jrockit/geninfo/diagnos/thread_basics.html
+
+* http://www.blogjava.net/security/archive/2009/02/16/jvm_thin-lock_fat-lock__spin-lock_tasuki-lock.html
+
+* https://www.zhihu.com/question/38857029
+
+* http://www.cnblogs.com/paddix/p/5405678.html
+
+* [Starvation and Fairness](http://tutorials.jenkov.com/java-concurrency/starvation-and-fairness.html)
+
+
diff --git "a/Java-Advanced/30.\343\200\212\344\272\277\347\272\247\346\265\201\351\207\217\347\275\221\347\253\231\346\236\266\346\236\204\346\240\270\345\277\203\346\212\200\346\234\257\343\200\213.mmap" "b/Java-Advanced/30.\343\200\212\344\272\277\347\272\247\346\265\201\351\207\217\347\275\221\347\253\231\346\236\266\346\236\204\346\240\270\345\277\203\346\212\200\346\234\257\343\200\213.mmap"
new file mode 100644
index 0000000..81338f7
Binary files /dev/null and "b/Java-Advanced/30.\343\200\212\344\272\277\347\272\247\346\265\201\351\207\217\347\275\221\347\253\231\346\236\266\346\236\204\346\240\270\345\277\203\346\212\200\346\234\257\343\200\213.mmap" differ
diff --git "a/Java-Advanced/31.Kafka\344\275\277\347\224\250.md" "b/Java-Advanced/31.Kafka\344\275\277\347\224\250.md"
new file mode 100644
index 0000000..7c6ca55
--- /dev/null
+++ "b/Java-Advanced/31.Kafka\344\275\277\347\224\250.md"
@@ -0,0 +1,6 @@
+# Kafka使用
+
+## Kafka安装和运行
+
+* 优先参考:https://www.vultr.com/docs/how-to-install-apache-kafka-on-centos-7
+* 官网:http://kafka.apache.org/090/documentation.html
diff --git "a/Java-Advanced/32.Java\346\227\245\345\277\227\346\234\200\344\275\263\345\256\236\350\267\265.md" "b/Java-Advanced/32.Java\346\227\245\345\277\227\346\234\200\344\275\263\345\256\236\350\267\265.md"
new file mode 100644
index 0000000..3a982cf
--- /dev/null
+++ "b/Java-Advanced/32.Java\346\227\245\345\277\227\346\234\200\344\275\263\345\256\236\350\267\265.md"
@@ -0,0 +1,83 @@
+# Java日志最佳实践
+
+## 接口和实现
+
+目前Java有三个比较常用的日志接口,分别为:JCL、SL4J、Log4j2-API,四个比较常用的具体实现:Log4j、JUL、Logback、Log4j2。在开发过程中,尽可能地依赖接口而不是实现编程。
+
+## Maven依赖
+
+具体的日志实现依赖应该设置为optional和使用runtime scope。
+
+设为optional,依赖不会传递,当应用达成jar包被其他项目引用时,会引入log的实现。
+
+scope设置为runtime,是为了防止开发人员在项目中直接使用具体的实现类。
+
+## 性能
+
+以打印json数据为例,在以前我们可能这样写:
+
+```Java
+log.debug("buy goods: " + toJson(goods));
+```
+这里有个性能问题,当我们把日志级别调到info之后,这里的json序列化和字符串拼接依然避免不了。 所以,后面有类似占位符之列的实现:
+
+```Java
+log.debug("buy goods:{}", toJson(goods));
+```
+但是依然无法避免json序列化的无用功,所以,我们可能会这样写:
+
+```Java
+if(log.debugEnabled()){
+ log.debug("buy goods:{}", toJson(goods));
+}
+```
+
+虽然代码冗余,但也较好地实现了需求。而从Java8开始后,Log4j2提供了lambda的实现,如下:
+
+```Java
+log.debug("buy goods:{}", () -> toJson(goods));
+```
+
+## 可读性-规范
+
+日志尽量提供有用的信息,避免过于简单但无用,量大而冗余。
+
+反面:
+
+```Java
+log.info("buy goods");
+```
+
+这里除了打印,基本不提供任何有效的信息,不利于追踪和debug。
+
+正面:
+
+```Java
+log.info("bug goods:[userId={},goodsId={},price={}]", userId, goodsId, price)
+```
+尽量提供有效的信息,方便跟踪和debug。
+
+## 日志级别
+
+针对不同的环境配置不同的日志文件。推荐如下:
+
+* 开发环境下,第三方jar包使用info级别,应用使用debug级别;
+* 生产环境下,第三方jar包使用warm级别,应用使用info级别;
+* 可以通过maven针对不同环境进行配置,避免上线手动修改;
+* 生产环境下,尽量避免打印包名、类名、方法名和代码行数,stacktrace代价昂贵。
+
+## 大小写问题
+
+有些人用LOG/LOGGER,有些人用log/logger。那哪个更合适呢?
+
+说到底,log有自己的状态,状态也会改变,并不属于常量,应该用小写更为合适。
+
+## 分布式系统
+
+## Lombok
+
+## 参考资料
+
+* https://zhuanlan.zhihu.com/p/24272450
+* https://zhuanlan.zhihu.com/p/24275518
+* http://www.importnew.com/17315.html
diff --git "a/Java-Advanced/32.\346\234\215\345\212\241\345\231\250CPU\346\240\270\345\277\203\346\225\260\345\257\271GC\347\232\204\345\275\261\345\223\215.md" "b/Java-Advanced/32.\346\234\215\345\212\241\345\231\250CPU\346\240\270\345\277\203\346\225\260\345\257\271GC\347\232\204\345\275\261\345\223\215.md"
new file mode 100644
index 0000000..c87f5b8
--- /dev/null
+++ "b/Java-Advanced/32.\346\234\215\345\212\241\345\231\250CPU\346\240\270\345\277\203\346\225\260\345\257\271GC\347\232\204\345\275\261\345\223\215.md"
@@ -0,0 +1,3 @@
+# 服务器CPU核心数对CPU的影响
+
+OpenJDK 64-Bit Server VM warning: If the number of processors is expected to increase from one, then you should configure the number of parallel GC threads appropriately using -XX:ParallelGCThreads=N
diff --git "a/Java-Advanced/33.\345\205\263\344\272\216\346\227\266\345\214\272\351\227\256\351\242\230.md" "b/Java-Advanced/33.\345\205\263\344\272\216\346\227\266\345\214\272\351\227\256\351\242\230.md"
new file mode 100644
index 0000000..56fd8d2
--- /dev/null
+++ "b/Java-Advanced/33.\345\205\263\344\272\216\346\227\266\345\214\272\351\227\256\351\242\230.md"
@@ -0,0 +1,39 @@
+# 关于时区问题
+
+## UTC,GMT,CST
+
+### UTC
+
+协调世界时(Coordinated Universal Time)是最主要的世界时间标准,其以原子时秒长为基础,在时刻上尽量接近于格林尼治标准时间。
+
+协调世界时是世界上调节时钟和时间的主要时间标准,它与0度经线的平太阳时相差不超过1秒,并不遵守夏令时。协调世界时是最接近格林威治标准时间(GMT)的几个替代时间系统之一。对于大多数用途来说,UTC时间被认为能与GMT时间互换,但GMT时间已不再被科学界所确定。
+
+### GMT
+格林尼治标准时间(Greenwich Mean Time,GMT)是指位于英国伦敦郊区的皇家格林尼治天文台当地的标准时间,因为本初子午线被定义为通过那里的经线。
+
+自1924年2月5日开始,格林尼治天文台负责每隔一小时向全世界发放调时信息。
+
+理论上来说,格林尼治标准时间的正午是指当太阳横穿格林尼治子午线时(也就是在格林尼治上空最高点时)的时间。但由于地球在它的椭圆轨道里的运动速度不均匀,这个时刻可能与实际的太阳时有误差,最大误差达16分钟。原因在于地球每天的自转是有些不规则的,而且正在缓慢减速,因此格林尼治时间基于天文观测本身的缺陷,已经不再被作为标准时间使用。现在的标准时间,是由原子钟报时的协调世界时(UTC)来决定。
+
+## CST
+
+CST可以指下列的时区:
+
+* 大中华地区时区
+* 北京时间,China Standard Time
+* 中原标准时间,Chungyuan Standard Time
+* 澳洲中部时间,Central Standard Time (Australia)
+* 北美中部时区,Central Standard Time (North America)
+* 古巴标准时间,Cuba Standard Time,参见北美东部时区
+
+## 时区对服务器的影响
+
+用户跟服务器在不同的时区。
+
+前端显示,提交日期。
+
+JSON的影响。
+
+## 时区对数据库的影响
+
+数据库复制备份时,master和slave处于不同的时区。
diff --git "a/Java-Advanced/34.\345\270\270\350\247\201\345\206\205\345\255\230\351\227\256\351\242\230.md" "b/Java-Advanced/34.\345\270\270\350\247\201\345\206\205\345\255\230\351\227\256\351\242\230.md"
new file mode 100644
index 0000000..724c614
--- /dev/null
+++ "b/Java-Advanced/34.\345\270\270\350\247\201\345\206\205\345\255\230\351\227\256\351\242\230.md"
@@ -0,0 +1,37 @@
+# 常见内存问题
+
+## OutOfMemory
+
+### java.lang.OutOfMemoryError: Java heap space
+
+### java.lang.OutOfMemoryError: GC Overhead limit exceeded
+
+By default, the Java process recovers less than 2 percent of the heap by spending more than 98 percent of its processing time. When this happens, it throws the GC overhead limit exceeded error.
+
+### java.lang.OutOfMemoryError: Permgen space
+
+This is applicable to JVM 7 and earlier. Java 8 has changed the memory model.
+
+This newer model does not have permanent generation region, which is replaced by Metaspace region. As we have learned, Java memory is divided into various regions. When JVM first initialized, it set the sizes of all these regions to platform-specific defaults. You can also specify the sizes in the VM parameter section, which will be used for the allocation over the platform-specific defaults. The preceding error is related to permanent generation area, which means the size of the permanent generation area in the memory is filled up. Permanent generation mostly stores the declarations, including name and fields of the class, methods with their bytecode, object arrays, constant pool information, and JIT compiler optimization of the loaded classes. This states that the permanent generation space is mainly affected by the number of classes and the size of each class. It means that a very big class or large number of classes are going to contribute to this type of error, OutOfMemoryError.
+
+### java.lang.OutOfMemoryError: Metaspace
+
+One of the regions of the JVM memory is the Metaspace region. If it gets filled up, JVM throws this type of exception. Since this is the replacement of the permanent generation region, the Metaspace region now stores the information of permanent generation. It is used to store things like the declarations, including name and fields of the class, methods with their bytecode, object arrays, constant pool information and JIT compiler optimization of the loaded classes.
+
+Hence, this type of error is thrown by JVM for having a large number of big classes. The following example uses javassist package from the link: http://jboss-javassist.github.io/javassist/ which enables Java bytecode manipulation. This library is used for editing bytecodes. At runtime when JVM loads the classes, programs can define or modify new classes:
+
+### java.lang.OutOfMemoryError: Unable to create new native thread
+
+As you know every Java program runs in a new thread. Java supports multithreading so you can create as many threads as you like till you consume all the available memory for the JVM. Once the memory limit is reached, JVM native code can no longer create a new native thread from the underlying operating system.
+
+### java.lang.OutOfMemoryError: request size bytes for reason
+
+If you are not new to computers, you may already know what swap space is. It is a space used by the underlying operating system to store the contents in lieu of RAM in case it fills up. Every time you start your application, JVM allocates the appropriate amount of memory to all the regions depending on your VM parameter. This means, your application has an upper limit for the memory it can use. Hence, if your application happens to request more memory than the allocated limit, the operating system uses the swap space from the hard drive as a virtual memory. If the swap memory space is also fully consumed, JVM throws the error java.lang.OutOfMemoryError: request size bytes for reason. Are you out of swap space?
+
+### java.lang.OutOfMemoryError: Requested array size exceeds VM limit
+
+This error is thrown by the operating system. The operating system has processes which are governed by various kernel jobs. One of these jobs is out of memory killer. This job monitors the low memory situation and kills the rogue process which is consuming more memory resources.
+
+### Out of memory: kill process or sacrifice child
+
+## StackOverflow
diff --git "a/Java-Advanced/35.Kafka\351\227\256\351\242\230\346\200\273\347\273\223.md" "b/Java-Advanced/35.Kafka\351\227\256\351\242\230\346\200\273\347\273\223.md"
new file mode 100644
index 0000000..ab87b59
--- /dev/null
+++ "b/Java-Advanced/35.Kafka\351\227\256\351\242\230\346\200\273\347\273\223.md"
@@ -0,0 +1,16 @@
+## spring.kafka.listener.concurrency大于partitions导致数据一直重复消费
+
+样例数据:
+
+```txt
+[{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}},{"date":1520395152252,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395453053,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395753815,"host":"74.121.148.194","content":{"2222":1428}},{"date":1520395838473,"host":"74.121.148.194","content":{"2222":63}},{"date":1520395598921,"host":"74.121.148.194","content":{"2222":6777}}]
+
+## 重复收到之前消息的问题
+
+https://www.jianshu.com/p/9b444d4b32c0
+```
+
+## kafka无限循环消息问题
+
+https://www.jianshu.com/p/4e00dff97f39
+
diff --git a/Java-Advanced/README.md b/Java-Advanced/README.md
new file mode 100644
index 0000000..7e59600
--- /dev/null
+++ b/Java-Advanced/README.md
@@ -0,0 +1 @@
+# README
diff --git a/Java-Advanced/img/ThreadStatesLifeCycle.png b/Java-Advanced/img/ThreadStatesLifeCycle.png
new file mode 100644
index 0000000..dd6d985
Binary files /dev/null and b/Java-Advanced/img/ThreadStatesLifeCycle.png differ
diff --git a/Java-Advanced/img/backlog.jpg b/Java-Advanced/img/backlog.jpg
new file mode 100644
index 0000000..44fa1a9
Binary files /dev/null and b/Java-Advanced/img/backlog.jpg differ
diff --git a/Java-Advanced/img/tcp-close_wait-time_wait.jpg b/Java-Advanced/img/tcp-close_wait-time_wait.jpg
new file mode 100644
index 0000000..5ea3faa
Binary files /dev/null and b/Java-Advanced/img/tcp-close_wait-time_wait.jpg differ
diff --git a/Java-Advanced/img/tcp_ladder_states.png b/Java-Advanced/img/tcp_ladder_states.png
new file mode 100644
index 0000000..b7bdee3
Binary files /dev/null and b/Java-Advanced/img/tcp_ladder_states.png differ
diff --git "a/Java-Base/00-\345\277\265\345\277\265\347\242\216.md" "b/Java-Base/00-\345\277\265\345\277\265\347\242\216.md"
new file mode 100644
index 0000000..b96e4ce
--- /dev/null
+++ "b/Java-Base/00-\345\277\265\345\277\265\347\242\216.md"
@@ -0,0 +1,3 @@
+# 念念碎
+
+* 浮点数除以0不会抛出**ArithmeticException**;
diff --git "a/Java-Base/00.\345\276\205\350\247\243\345\206\263\351\227\256\351\242\230.md" "b/Java-Base/00.\345\276\205\350\247\243\345\206\263\351\227\256\351\242\230.md"
new file mode 100644
index 0000000..93703e9
--- /dev/null
+++ "b/Java-Base/00.\345\276\205\350\247\243\345\206\263\351\227\256\351\242\230.md"
@@ -0,0 +1,2 @@
+#00.待解决问题
+
diff --git "a/01.\344\275\277\347\224\250socket\345\217\221\351\200\201HTTP GET\350\257\267\346\261\202.md" "b/Java-Base/01.\344\275\277\347\224\250socket\345\217\221\351\200\201HTTP GET\350\257\267\346\261\202.md"
similarity index 98%
rename from "01.\344\275\277\347\224\250socket\345\217\221\351\200\201HTTP GET\350\257\267\346\261\202.md"
rename to "Java-Base/01.\344\275\277\347\224\250socket\345\217\221\351\200\201HTTP GET\350\257\267\346\261\202.md"
index d454690..e0adf47 100644
--- "a/01.\344\275\277\347\224\250socket\345\217\221\351\200\201HTTP GET\350\257\267\346\261\202.md"
+++ "b/Java-Base/01.\344\275\277\347\224\250socket\345\217\221\351\200\201HTTP GET\350\257\267\346\261\202.md"
@@ -1,59 +1,59 @@
-#01.使用socket发送HTTP GET请求
-
-##1.HTTP协议介绍
- HTTP是建立在TCP/IP之上,用于互联网上超媒体系统应用之间的通信协议。中文奶名:超文本传输协议。
-
- 简单地说,HTTP就是建立在TCP/IP之上,使用一些特殊的文本标志来进行客户端与服务器端的通信。
-
- 这些特殊的标志文本,包括三个部分:Start line,Header,Body。
-
- 客户端发送给服务器(Request请求)以及服务器返回给客户端(Response响应)的特殊标志文本不尽相同,例如Request与Response的
- Start Line是不同的,Request与Response的Header有公用的部分,也有自己私有的Header。下面这张图是一个HTTP GET Request以及服务
- 器的Response。
-
-  -
- 需要注意都是,GET请求没有Body。
-
-##2.HTTP GET请求
- 如上面所说,HTTP是建立在TCP/IP之上使用一些标识文本来进行通信的协议,只要我们按照一定的格式发送这些标识文本,就可以跟
- HTTP服务器进行通讯了。例如下面是一个HTTP GET请求的标识文本:
-
- GET /index.html HTTP/1.1
- Host: www.allwinnertech.com
-
-
- 上面这个,基本是HTTP GET请求所需的最少的标识文本,只包括Start line和一个Header属性(GET请求没有Body)。
-
- 第一行为Start line,这里表示是一个基于HTTP 1.1版本的GET请求,需要获取的资源为Host所标识的服务器下的index.html文本。
-
- 第二行到回车换行符行(这里是第三行)前都是Header,Header的Host属性表明访问的域名为www.allwinnertech.com。
-
- 这里的第三行为一个回车换行符,用于标识Header与Body的界线,由于GET请求没有Body,所以这里的最后一行为回车换行符。
-
- 我们只要在TCP连接之上,按照这个格式发送文本,就可以取得www.allwinnertech.co/index.html这个文本了。
-
-##3.使用Socket发送HTTP GET请求
- 这里尽量使用最少的代码量来实现HTTP GET请求,不会考虑长连接(一次TCP连接,多次HTTP请求),以及WebSocket(一次Request,
- 多次Reponse)等请求。这里只是发送一次HTTP请求,然后读取取得的文本(更像HTTP 1.0)。
-
-```java
-Socket socket = new Socket("www.allwinnertech.com", 80); // 建立socket连接
-
-BufferedWriter bw = new BufferedWriter(new OutputStreamWriter(socket.getOutputStream())); // 取得文本输出流
-
-bw.write("GET / HTTP/1.1\r\n"); // \r\n为回车换行符
-bw.write("Host: www.allwinnertech.com\r\n");
-bw.write("\r\n"); // 不要忘记Header之后还有一个回车换行符
-bw.flush(); // 发送请求
-
-BufferedReader br = new BufferedReader(new InputStreamReader(socket.getInputStream())); // 取得文本输出流
-
-String line = null;
-while((line = br.readLine())!=null) { //迭代输出的文本
- System.out.println(line);
-}
-```
- 将这段代码运行之后,就可以在控制台看到取得文本了。
-
- 就那么简单!
+#01.使用socket发送HTTP GET请求
+
+##1.HTTP协议介绍
+ HTTP是建立在TCP/IP之上,用于互联网上超媒体系统应用之间的通信协议。中文奶名:超文本传输协议。
+
+ 简单地说,HTTP就是建立在TCP/IP之上,使用一些特殊的文本标志来进行客户端与服务器端的通信。
+
+ 这些特殊的标志文本,包括三个部分:Start line,Header,Body。
+
+ 客户端发送给服务器(Request请求)以及服务器返回给客户端(Response响应)的特殊标志文本不尽相同,例如Request与Response的
+ Start Line是不同的,Request与Response的Header有公用的部分,也有自己私有的Header。下面这张图是一个HTTP GET Request以及服务
+ 器的Response。
+
+
+
+ 需要注意都是,GET请求没有Body。
+
+##2.HTTP GET请求
+ 如上面所说,HTTP是建立在TCP/IP之上使用一些标识文本来进行通信的协议,只要我们按照一定的格式发送这些标识文本,就可以跟
+ HTTP服务器进行通讯了。例如下面是一个HTTP GET请求的标识文本:
+
+ GET /index.html HTTP/1.1
+ Host: www.allwinnertech.com
+
+
+ 上面这个,基本是HTTP GET请求所需的最少的标识文本,只包括Start line和一个Header属性(GET请求没有Body)。
+
+ 第一行为Start line,这里表示是一个基于HTTP 1.1版本的GET请求,需要获取的资源为Host所标识的服务器下的index.html文本。
+
+ 第二行到回车换行符行(这里是第三行)前都是Header,Header的Host属性表明访问的域名为www.allwinnertech.com。
+
+ 这里的第三行为一个回车换行符,用于标识Header与Body的界线,由于GET请求没有Body,所以这里的最后一行为回车换行符。
+
+ 我们只要在TCP连接之上,按照这个格式发送文本,就可以取得www.allwinnertech.co/index.html这个文本了。
+
+##3.使用Socket发送HTTP GET请求
+ 这里尽量使用最少的代码量来实现HTTP GET请求,不会考虑长连接(一次TCP连接,多次HTTP请求),以及WebSocket(一次Request,
+ 多次Reponse)等请求。这里只是发送一次HTTP请求,然后读取取得的文本(更像HTTP 1.0)。
+
+```java
+Socket socket = new Socket("www.allwinnertech.com", 80); // 建立socket连接
+
+BufferedWriter bw = new BufferedWriter(new OutputStreamWriter(socket.getOutputStream())); // 取得文本输出流
+
+bw.write("GET / HTTP/1.1\r\n"); // \r\n为回车换行符
+bw.write("Host: www.allwinnertech.com\r\n");
+bw.write("\r\n"); // 不要忘记Header之后还有一个回车换行符
+bw.flush(); // 发送请求
+
+BufferedReader br = new BufferedReader(new InputStreamReader(socket.getInputStream())); // 取得文本输出流
+
+String line = null;
+while((line = br.readLine())!=null) { //迭代输出的文本
+ System.out.println(line);
+}
+```
+ 将这段代码运行之后,就可以在控制台看到取得文本了。
+
+ 就那么简单!
diff --git "a/02.\347\274\226\345\206\231\350\207\252\345\256\232\344\271\211Annotation.md" "b/Java-Base/02.\347\274\226\345\206\231\350\207\252\345\256\232\344\271\211Annotation.md"
similarity index 99%
rename from "02.\347\274\226\345\206\231\350\207\252\345\256\232\344\271\211Annotation.md"
rename to "Java-Base/02.\347\274\226\345\206\231\350\207\252\345\256\232\344\271\211Annotation.md"
index fbe3f55..06afcd1 100644
--- "a/02.\347\274\226\345\206\231\350\207\252\345\256\232\344\271\211Annotation.md"
+++ "b/Java-Base/02.\347\274\226\345\206\231\350\207\252\345\256\232\344\271\211Annotation.md"
@@ -18,7 +18,7 @@ public @interface TestCase { // 使用@Interface修饰这个是一个Annotation
以上就完成了一个Annotation接口的编写。接着我们写一个Test类来使用@TestCase这个注释。
```java
public class Test {
- @TestCase
+
public void m_1(){
System.out.println("This is Method with @TestCase!");
}
diff --git "a/03.\350\233\213\347\226\274\347\232\204AOP\346\246\202\345\277\265.md" "b/Java-Base/03.\350\233\213\347\226\274\347\232\204AOP\346\246\202\345\277\265.md"
similarity index 95%
rename from "03.\350\233\213\347\226\274\347\232\204AOP\346\246\202\345\277\265.md"
rename to "Java-Base/03.\350\233\213\347\226\274\347\232\204AOP\346\246\202\345\277\265.md"
index 94c614f..6e24207 100644
--- "a/03.\350\233\213\347\226\274\347\232\204AOP\346\246\202\345\277\265.md"
+++ "b/Java-Base/03.\350\233\213\347\226\274\347\232\204AOP\346\246\202\345\277\265.md"
@@ -1,6 +1,6 @@
#AOP介绍
-AOP全称Aspect Oriented Programming,面向切面编程。在事务管理,代码跟踪方面应用很广泛。教科书上的对于AOP概念的解释比较让人晕眩,下面是偶本人对AOP一些概念的理解:
+AOP全称Aspect Oriented Programming,面向切面编程。在事务管理,代码跟踪方面应用很广泛。教科书上的对于AOP概念的解释比较让人晕眩。
>**连接点(Joinpoint)**:程序流中可以用于代码植入的点,通常是某些边界,例如:类初始化前、类初始化后、方法执行前、方法执行后、方法抛异常后。
diff --git "a/04.AOP\347\232\204\345\272\224\347\224\250\350\214\203\345\233\264\345\217\212\345\256\236\347\216\260\346\241\206\346\236\266.md" "b/Java-Base/04.AOP\347\232\204\345\272\224\347\224\250\350\214\203\345\233\264\345\217\212\345\256\236\347\216\260\346\241\206\346\236\266.md"
similarity index 100%
rename from "04.AOP\347\232\204\345\272\224\347\224\250\350\214\203\345\233\264\345\217\212\345\256\236\347\216\260\346\241\206\346\236\266.md"
rename to "Java-Base/04.AOP\347\232\204\345\272\224\347\224\250\350\214\203\345\233\264\345\217\212\345\256\236\347\216\260\346\241\206\346\236\266.md"
diff --git "a/05.\350\243\205\351\245\260\345\231\250\346\250\241\345\274\217.md" "b/Java-Base/05.\350\243\205\351\245\260\345\231\250\346\250\241\345\274\217.md"
similarity index 97%
rename from "05.\350\243\205\351\245\260\345\231\250\346\250\241\345\274\217.md"
rename to "Java-Base/05.\350\243\205\351\245\260\345\231\250\346\250\241\345\274\217.md"
index 4876258..78fc517 100644
--- "a/05.\350\243\205\351\245\260\345\231\250\346\250\241\345\274\217.md"
+++ "b/Java-Base/05.\350\243\205\351\245\260\345\231\250\346\250\241\345\274\217.md"
@@ -2,9 +2,6 @@
## 遇到的问题
- 学习的最好方法就是实践,想当年大学学《设计模式》这门课的时候,重修两次,补考还挂了两次,最后还是甩小聪明才拿到的毕业证。
-往事不多提,甚是可悲。
-
最近遇到一个问题,这里有一个controller的方法,方法里面需要获取request header的 __x-forwarded-for__ 属性的值:
```java
diff --git "a/06.\345\215\225\344\276\213\346\250\241\345\274\217.md" "b/Java-Base/06.\345\215\225\344\276\213\346\250\241\345\274\217.md"
similarity index 86%
rename from "06.\345\215\225\344\276\213\346\250\241\345\274\217.md"
rename to "Java-Base/06.\345\215\225\344\276\213\346\250\241\345\274\217.md"
index b4dea4a..b1a2a1e 100644
--- "a/06.\345\215\225\344\276\213\346\250\241\345\274\217.md"
+++ "b/Java-Base/06.\345\215\225\344\276\213\346\250\241\345\274\217.md"
@@ -4,7 +4,7 @@
在我们需要在系统中只能拥有一个实例时,这时候我们就需要单例模式,例如:数据库连接池、缓存池等。
-##6.1 最简单的单例模式
+## 6.1最简单的单例模式
在读书的时候,或许我们都写过这么一个单例的实现:
@@ -24,7 +24,7 @@ public class DataSource {
类提供了一个getInstance方法,该方法返回一个在类加载期就初始化的DataSource实例化对象,从而保证了DataSource实例的唯一性。
-##6.2 延迟创建
+## 6.2延迟创建
我们知道static标识的属性会在类初始时就进行初始化。处于性能的考虑,我们可能会希望该单例的实例化对象,在第一次使用的时候再进行初始化:
@@ -48,7 +48,7 @@ public class DataSource {
我们将DataSource的初始化迁移到getInstance方法里,系统会第一次调用getInstance方法的时候初始化DataSource对象。
-##6.3 线程安全
+## 6.3线程安全
上面的例子中,细心的人或许会发现:在多线程的情况下,如果第一次有N个线程同时进入getInstance方法,则会产生线程安全问题,
会多次创建DataSource对象,甚至其他问题。
@@ -71,7 +71,7 @@ public class DataSource {
}
```
-##6.3 线程安全优化
+## 6.3线程安全优化
也许有人有提出问题了,在高并发的情况下,使用synchronized对整个方法进行同步会影响性能(大多数情况下没必要计较)。
@@ -79,7 +79,8 @@ public class DataSource {
```java
public class DataSource {
- private static DataSource dataSource = null;
+ // volatile关键字必不可少
+ private volatile static DataSource dataSource = null;
private DataSource() {}
@@ -99,9 +100,22 @@ public class DataSource {
在这个实现里使用了 **double check** (两次判断dataSource == null)。当多个线程同时进入第一个if判断时,double check是很有必要滴!
-##6.4 静态内部类
+## 6.4静态内部类
+
+```
+public class Singleton{
+ public static class SingletonHolder {
+ private static final Singleton INSTANCE = new Singleton();
+ }
+ private Singleton(){}
+ public static Singleton getInstance(){
+ return SingletonHolder.INSTANCE;
+ }
+}
+```
+
-##6.5 序列化
+## 6.5 序列化
## 参考资料
diff --git "a/07.\344\275\277\347\224\250socket\345\217\221\351\200\201HTTP POST\350\257\267\346\261\202.md" "b/Java-Base/07.\344\275\277\347\224\250socket\345\217\221\351\200\201HTTP POST\350\257\267\346\261\202.md"
similarity index 79%
rename from "07.\344\275\277\347\224\250socket\345\217\221\351\200\201HTTP POST\350\257\267\346\261\202.md"
rename to "Java-Base/07.\344\275\277\347\224\250socket\345\217\221\351\200\201HTTP POST\350\257\267\346\261\202.md"
index f5757b2..900f70a 100644
--- "a/07.\344\275\277\347\224\250socket\345\217\221\351\200\201HTTP POST\350\257\267\346\261\202.md"
+++ "b/Java-Base/07.\344\275\277\347\224\250socket\345\217\221\351\200\201HTTP POST\350\257\267\346\261\202.md"
@@ -54,16 +54,3 @@ socket.close();
```
一个HTTP POST的登陆请求就完成了。Java代码不难实现,唯一需要注意的HTTP报文的格式了。
-
-##Connection: close
-
- 细心的人,可能会发现上面的请求,控制台虽然正确地打印了服务器响应的登陆报文,但是控制台的线程是还没有断开的。
-即使客户端使用了
socket.close()。
-
- 这里涉及TCP协议以及HTTP 1.1的长连接,先不详细解释。这里我们简单地使用一个Header就可以断开请求了。
-
-```java
-bw.write("Connection: close\r\n");
-```
-
- 把上面这一段代码复制到前面一段代码的Header部分即可。perfect!
diff --git "a/08.\350\264\253\350\241\200\346\250\241\345\236\213\344\270\216\345\205\205\350\241\200\346\250\241\345\236\213.md" "b/Java-Base/08.\350\264\253\350\241\200\346\250\241\345\236\213\344\270\216\345\205\205\350\241\200\346\250\241\345\236\213.md"
similarity index 100%
rename from "08.\350\264\253\350\241\200\346\250\241\345\236\213\344\270\216\345\205\205\350\241\200\346\250\241\345\236\213.md"
rename to "Java-Base/08.\350\264\253\350\241\200\346\250\241\345\236\213\344\270\216\345\205\205\350\241\200\346\250\241\345\236\213.md"
diff --git "a/09.\350\256\250\345\216\214\347\232\204setter\345\222\214getter.md" "b/Java-Base/09.\350\256\250\345\216\214\347\232\204setter\345\222\214getter.md"
similarity index 100%
rename from "09.\350\256\250\345\216\214\347\232\204setter\345\222\214getter.md"
rename to "Java-Base/09.\350\256\250\345\216\214\347\232\204setter\345\222\214getter.md"
diff --git "a/10.Java8\344\271\213Lambda\350\241\250\350\276\276\345\274\217.md" "b/Java-Base/10.Java8\344\271\213Lambda\350\241\250\350\276\276\345\274\217.md"
similarity index 100%
rename from "10.Java8\344\271\213Lambda\350\241\250\350\276\276\345\274\217.md"
rename to "Java-Base/10.Java8\344\271\213Lambda\350\241\250\350\276\276\345\274\217.md"
diff --git "a/11.\344\272\213\345\212\241\347\232\204\344\274\240\346\222\255\346\234\272\345\210\266\344\270\216\351\232\224\347\246\273\347\272\247\345\210\253.md" "b/Java-Base/11.\344\272\213\345\212\241\347\232\204\344\274\240\346\222\255\346\234\272\345\210\266\344\270\216\351\232\224\347\246\273\347\272\247\345\210\253.md"
similarity index 97%
rename from "11.\344\272\213\345\212\241\347\232\204\344\274\240\346\222\255\346\234\272\345\210\266\344\270\216\351\232\224\347\246\273\347\272\247\345\210\253.md"
rename to "Java-Base/11.\344\272\213\345\212\241\347\232\204\344\274\240\346\222\255\346\234\272\345\210\266\344\270\216\351\232\224\347\246\273\347\272\247\345\210\253.md"
index 06cbb72..241777d 100644
--- "a/11.\344\272\213\345\212\241\347\232\204\344\274\240\346\222\255\346\234\272\345\210\266\344\270\216\351\232\224\347\246\273\347\272\247\345\210\253.md"
+++ "b/Java-Base/11.\344\272\213\345\212\241\347\232\204\344\274\240\346\222\255\346\234\272\345\210\266\344\270\216\351\232\224\347\246\273\347\272\247\345\210\253.md"
@@ -36,6 +36,14 @@ __可序列化(Serializable)__ |最高的隔离级别,保证所有的事
EJB和Spring的这些事务隔离设置依赖于底层数据库。也就是说,虽然编程框架支持上述种种隔离级别设定,但需要底层数据库也要支持这些级别设定,设定才会生效。如果数据库不支持某一个设定级别,而应用框架这样设置了,数据库将会采用缺省的隔离级别。
+##11.3 脏读、幻读、不可重复读等定义
+
+### 脏读
+
+### 幻读
+
+### 不可重复读
+
## 参考资料
* http://docs.oracle.com/cd/E19226-01/820-7627/6nisfjnao/index.html
diff --git a/12.Spring MVC WebApplicationContext.md b/Java-Base/12.Spring MVC WebApplicationContext.md
similarity index 100%
rename from 12.Spring MVC WebApplicationContext.md
rename to Java-Base/12.Spring MVC WebApplicationContext.md
diff --git "a/13.\344\270\215\350\246\201\345\234\250HttpSession\345\214\205\344\277\235\345\255\230\351\235\236\345\272\217\345\210\227\345\214\226\345\257\271\350\261\241.md" "b/Java-Base/13.\344\270\215\350\246\201\345\234\250HttpSession\345\214\205\344\277\235\345\255\230\351\235\236\345\272\217\345\210\227\345\214\226\345\257\271\350\261\241.md"
similarity index 100%
rename from "13.\344\270\215\350\246\201\345\234\250HttpSession\345\214\205\344\277\235\345\255\230\351\235\236\345\272\217\345\210\227\345\214\226\345\257\271\350\261\241.md"
rename to "Java-Base/13.\344\270\215\350\246\201\345\234\250HttpSession\345\214\205\344\277\235\345\255\230\351\235\236\345\272\217\345\210\227\345\214\226\345\257\271\350\261\241.md"
diff --git "a/14.SimpleDateFormat\351\235\236\347\272\277\347\250\213\345\256\211\345\205\250.md" "b/Java-Base/14.SimpleDateFormat\351\235\236\347\272\277\347\250\213\345\256\211\345\205\250.md"
similarity index 100%
rename from "14.SimpleDateFormat\351\235\236\347\272\277\347\250\213\345\256\211\345\205\250.md"
rename to "Java-Base/14.SimpleDateFormat\351\235\236\347\272\277\347\250\213\345\256\211\345\205\250.md"
diff --git "a/15.HTTP\344\271\213\346\214\201\344\271\205\350\277\236\346\216\245.md" "b/Java-Base/15.HTTP\344\271\213\346\214\201\344\271\205\350\277\236\346\216\245.md"
similarity index 100%
rename from "15.HTTP\344\271\213\346\214\201\344\271\205\350\277\236\346\216\245.md"
rename to "Java-Base/15.HTTP\344\271\213\346\214\201\344\271\205\350\277\236\346\216\245.md"
diff --git "a/16.\347\224\237\344\272\247\350\200\205\346\266\210\350\264\271\350\200\205\346\250\241\345\274\217.md" "b/Java-Base/16.\347\224\237\344\272\247\350\200\205\346\266\210\350\264\271\350\200\205\346\250\241\345\274\217.md"
similarity index 100%
rename from "16.\347\224\237\344\272\247\350\200\205\346\266\210\350\264\271\350\200\205\346\250\241\345\274\217.md"
rename to "Java-Base/16.\347\224\237\344\272\247\350\200\205\346\266\210\350\264\271\350\200\205\346\250\241\345\274\217.md"
diff --git "a/17.\350\277\252\347\261\263\347\211\271\346\263\225\345\210\231\357\274\210\345\276\227\345\242\250\345\277\222\350\200\263\345\256\232\345\276\213\357\274\211.md" "b/Java-Base/17.\350\277\252\347\261\263\347\211\271\346\263\225\345\210\231\357\274\210\345\276\227\345\242\250\345\277\222\350\200\263\345\256\232\345\276\213\357\274\211.md"
similarity index 100%
rename from "17.\350\277\252\347\261\263\347\211\271\346\263\225\345\210\231\357\274\210\345\276\227\345\242\250\345\277\222\350\200\263\345\256\232\345\276\213\357\274\211.md"
rename to "Java-Base/17.\350\277\252\347\261\263\347\211\271\346\263\225\345\210\231\357\274\210\345\276\227\345\242\250\345\277\222\350\200\263\345\256\232\345\276\213\357\274\211.md"
diff --git "a/18.REST\346\236\266\346\236\204\351\243\216\346\240\274.md" "b/Java-Base/18.REST\346\236\266\346\236\204\351\243\216\346\240\274.md"
similarity index 92%
rename from "18.REST\346\236\266\346\236\204\351\243\216\346\240\274.md"
rename to "Java-Base/18.REST\346\236\266\346\236\204\351\243\216\346\240\274.md"
index 2b52ce0..23440db 100644
--- "a/18.REST\346\236\266\346\236\204\351\243\216\346\240\274.md"
+++ "b/Java-Base/18.REST\346\236\266\346\236\204\351\243\216\346\240\274.md"
@@ -1,8 +1,8 @@
-#18.REST架构风格
+# 18.REST架构风格
从毕业设计误打误撞选了《RESTful架构webservice应用研究》这个课题,到现在也三年有多了。但直至目前,个人对REST的理解都还欠缺火候。随着知识的积累与深入,对同一个事务的认知都在变化。且让我把当前的想法记录下来,秋后才有账可算。:)
-##18.1 什么是REST
+## 18.1 什么是REST
__REST__,英文名叫__Representational State Transfer__,翻译为中文为__表述性状态转移__。okay,我们不要纠结与名词的含义,简而言之:REST就是利用__用户友好的URL风格__、利用现存的__HTTP动词__以及__HTTP相关的特性__来规范WebService接口。实际上它是一种交互数据的协议规范。
@@ -10,7 +10,7 @@ __REST__,英文名叫__Representational State Transfer__,翻译为中文为_
当然,我并不认为REST是一种架构,我更认同它是一种__设计风格或理念__。当大家都遵循这样的设计理念后,那么拓展、跨平台、维护也就水到渠成了(API文档都不用写了,呵呵)。
-##18.2 REST特性
+## 18.2 REST特性
REST是建立在HTTP之上的,所以REST的很多特征都与HTTP息息相关。
@@ -21,7 +21,7 @@ REST是建立在HTTP之上的,所以REST的很多特征都与HTTP息息相关
* 统一接口(Uniform Interface)
* 超文本驱动(Hypertext Driven)
-###18.2.1 面向资源(Resource Oriented)
+### 18.2.1 面向资源(Resource Oriented)
面向资源是REST最明显的特征,__每个URI都唯一指向一个资源,同时一个资源可以由多个URI表示__。
@@ -46,7 +46,7 @@ http://www.example.com/queryPage?bookId=2&pageNo=10086
* 容易理解
* 易于拓展
-###18.2.2 可寻址(Addressability)
+### 18.2.2 可寻址(Addressability)
每一个资源都有一个唯一的URI标识。我们可以根据URI找到相应的资源。甚至,我们可以根据这些URI类比其他资源的地址。
@@ -54,15 +54,15 @@ http://www.example.com/queryPage?bookId=2&pageNo=10086
而实际上也正如我所想。(这是一个软件类的电子书网站,很强大,请笑纳: ))
-###18.2.3 连通性(Connectedness)
+### 18.2.3 连通性(Connectedness)
REST指出,资源不应该是孤立的,应该使用超链接将资源关联起来。这个概念很有意思,而实际上会被很多开发人员忽略。后面我们再来详细展开讨论。
-###18.2.4 无状态(Statelessness)
+### 18.2.4 无状态(Statelessness)
无状态性意味着每个HTTP请求都是彼此孤立,互不干扰的。REST的无状态性,让横向实现分布性系统提供了方便。URI在前面我们已经提过,这里来说一下HTTP方法。
-###18.2.5 统一接口(Uniform Interface)
+### 18.2.5 统一接口(Uniform Interface)
虽然浏览器只支持HTTP的GET和POST方法,我们也知道GET方法用来获取资源,而POST方法通常用来添加、修改和删除资源的。但是实际上HTTP为了我们提供了更有语义的方法。
@@ -78,18 +78,18 @@ HTTP还提供了其他的HTTP方法,这里不再累赘,只叙述CRUD。
可以看到REST是使用现成的HTTP方法来更新资源的状态(这就是__状态转移__之意),增删改查分别对应POST、DELETE、PUT和GET方法。相比我们以前使用的动词,如_delBook_、_deleteBook_、_removeBook_、_book?operation=delete_等等。REST实在太高上大了。
-####18.2.5.1 使用HTTP动词的优势
+#### 18.2.5.1 使用HTTP动词的优势
GET、POST、PUT、DELETE,幂等安全等特性。
客户端与服务器之间通过特定的URI和HTTP方法进行交互。
-###18.2.6 超文本驱动(Hypertext Driven)
+### 18.2.6 超文本驱动(Hypertext Driven)
-##18.3 URL设计(事实上的妥协)
+## 18.3 URL设计(事实上的妥协)
-##18.4 REST优势
+## 18.4 REST优势
-##18.5 参考资料
+## 18.5 参考资料
* http://www.infoq.com/cn/articles/understanding-restful-style
* http://www.ruanyifeng.com/blog/2011/09/restful.html
diff --git "a/19.Java\345\257\271\350\261\241\345\272\217\345\210\227\345\214\226\344\270\216RMI.md" "b/Java-Base/19.Java\345\257\271\350\261\241\345\272\217\345\210\227\345\214\226\344\270\216RMI.md"
similarity index 100%
rename from "19.Java\345\257\271\350\261\241\345\272\217\345\210\227\345\214\226\344\270\216RMI.md"
rename to "Java-Base/19.Java\345\257\271\350\261\241\345\272\217\345\210\227\345\214\226\344\270\216RMI.md"
diff --git "a/20.Java7\344\271\213try-with-resources.md" "b/Java-Base/20.Java7\344\271\213try-with-resources.md"
similarity index 100%
rename from "20.Java7\344\271\213try-with-resources.md"
rename to "Java-Base/20.Java7\344\271\213try-with-resources.md"
diff --git "a/21.\345\274\202\345\270\270\346\234\200\344\275\263\345\256\236\350\267\265.md" "b/Java-Base/21.\345\274\202\345\270\270\346\234\200\344\275\263\345\256\236\350\267\265.md"
similarity index 100%
rename from "21.\345\274\202\345\270\270\346\234\200\344\275\263\345\256\236\350\267\265.md"
rename to "Java-Base/21.\345\274\202\345\270\270\346\234\200\344\275\263\345\256\236\350\267\265.md"
diff --git "a/22.\347\274\226\347\240\201\350\247\243\347\240\201.md" "b/Java-Base/22.\347\274\226\347\240\201\350\247\243\347\240\201.md"
similarity index 97%
rename from "22.\347\274\226\347\240\201\350\247\243\347\240\201.md"
rename to "Java-Base/22.\347\274\226\347\240\201\350\247\243\347\240\201.md"
index 689d289..5281478 100644
--- "a/22.\347\274\226\347\240\201\350\247\243\347\240\201.md"
+++ "b/Java-Base/22.\347\274\226\347\240\201\350\247\243\347\240\201.md"
@@ -9,7 +9,7 @@
```Java
System.out.println("中国");
```
-1. 无论文件以任何编码格式载入到JVM中,"中国"二字都会以unicode码的形式存在JVM中(\u4e2d\u56fd);
+1. 无论文本以任何编码格式载入到JVM中,"中国"二字都会以unicode码的形式存在JVM中(\u4e2d\u56fd);
2. 假如IDE控制台的编码为UTF-8,当对"中国"二字进行控制台输出时,系统会将unicode码转为具体的UTF-8编码格式。(\u4e2d\u56fd -> e4b8ade59bbd)
```
@@ -77,4 +77,4 @@ public void gbk_unicode_utf8() throws DecoderException,
实际上,这里的unicode编码对应的是unicode的`UTF-16`编码。以16位定长的二进制表示一个unicode码。
-## 参考资料
\ No newline at end of file
+## 参考资料
diff --git "a/23.\345\237\272\346\234\254\346\225\260\346\215\256\347\261\273\345\236\213\344\270\216\350\277\233\345\210\266\350\275\254\346\215\242.md" "b/Java-Base/23.\345\237\272\346\234\254\346\225\260\346\215\256\347\261\273\345\236\213\344\270\216\350\277\233\345\210\266\350\275\254\346\215\242.md"
similarity index 100%
rename from "23.\345\237\272\346\234\254\346\225\260\346\215\256\347\261\273\345\236\213\344\270\216\350\277\233\345\210\266\350\275\254\346\215\242.md"
rename to "Java-Base/23.\345\237\272\346\234\254\346\225\260\346\215\256\347\261\273\345\236\213\344\270\216\350\277\233\345\210\266\350\275\254\346\215\242.md"
diff --git "a/24.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213Base64.md" "b/Java-Base/24.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213Base64.md"
similarity index 100%
rename from "24.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213Base64.md"
rename to "Java-Base/24.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213Base64.md"
diff --git "a/25.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213JCA.md" "b/Java-Base/25.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213JCA.md"
similarity index 100%
rename from "25.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213JCA.md"
rename to "Java-Base/25.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213JCA.md"
diff --git "a/26.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\345\237\272\346\234\254\346\265\201\347\250\213.md" "b/Java-Base/26.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\345\237\272\346\234\254\346\265\201\347\250\213.md"
similarity index 100%
rename from "26.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\345\237\272\346\234\254\346\265\201\347\250\213.md"
rename to "Java-Base/26.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\345\237\272\346\234\254\346\265\201\347\250\213.md"
diff --git "a/27.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\345\257\271\347\247\260\345\212\240\345\257\206\347\256\227\346\263\225.md" "b/Java-Base/27.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\345\257\271\347\247\260\345\212\240\345\257\206\347\256\227\346\263\225.md"
similarity index 93%
rename from "27.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\345\257\271\347\247\260\345\212\240\345\257\206\347\256\227\346\263\225.md"
rename to "Java-Base/27.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\345\257\271\347\247\260\345\212\240\345\257\206\347\256\227\346\263\225.md"
index 567e86e..caaaded 100644
--- "a/27.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\345\257\271\347\247\260\345\212\240\345\257\206\347\256\227\346\263\225.md"
+++ "b/Java-Base/27.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\345\257\271\347\247\260\345\212\240\345\257\206\347\256\227\346\263\225.md"
@@ -6,7 +6,7 @@
**对称加密算法的安全基于密钥的保密,所以密钥的安全与否决定了加密信息的安全!**
-虽然说**对称加密算法**不适用于安全要求较高的场合,对是对于一般应用来说,这已经足够了。与此同时,对称加密的速度远由于非对称加密,所以还是很多场景适用对称加密。
+虽然说**对称加密算法**不适用于安全要求较高的场合,对是对于一般应用来说,这已经足够了。与此同时,对称加密的速度远低于非对称加密,所以还是很多场景适用对称加密。
对称加密的速度比公钥加密快很多,在很多场合都需要对称加密。
@@ -36,7 +36,7 @@ IDEA(International Data Encryption Algorithm,国际数据加密标准)是
在加密之前,我们先要生成加密算法对应的密钥。我们之前所说的密钥长度都是基于位元为单位的。例如128位的密钥,则该密钥占用128个位元,以一个字节八位元,128密钥占用128 / 8 = 16个字节。使用byte[]数组存放,则byte[]的长度为16。
-为了方便存储和传输,我们通常使用Base64对密钥的字节组数进行编码。而ASCII编码有很多字符是不可打印的,所以不建议使用ASCII。当然你可以使用ASCII,当时很容易在存储或传输过程中丢失字节(在计算器中存储和传输没有问题,但是使用纸质就歇菜了)。当然你可以使用其他方式和编码,一般情况下都是使用Base64,约定俗成。
+为了方便存储和传输,我们通常使用Base64对密钥的字节组数进行编码。而ASCII编码有很多字符是不可打印的,所以不建议使用ASCII。当然你可以使用ASCII,但是很容易在存储或传输过程中丢失字节(在计算器中存储和传输没有问题,但是使用纸质就歇菜了)。当然你可以使用其他方式和编码,一般情况下都是使用Base64,约定俗成。
Java中使用`KeyGenerator`类来生成密钥。如下:
@@ -58,7 +58,7 @@ public void generateKey() throws NoSuchAlgorithmException {
Cipher是JCA中用于加密解密的类,它同时负责数据的加密与解密。在初始化时,需要为Cipher指定是加密或是解密模式。
-加密与加密的过程直接操作的是数据的字节数组,由于字符在JVM中是以unicode形式存在的,字符串的不同编码的字节数组序列是一样的,例如UTF-8和GBK的字节序列就不一样。所以在加密之前或加密之后需要将字符编码进行编码与解码。当然,这不是必须的,你可以使用系统默认的ASCII字符编码,只要统一即可。
+加密与加密的过程直接操作的是数据的字节数组,由于字符在JVM中是以unicode形式存在的,字符串的不同编码的字节数组序列是不一样的,例如UTF-8和GBK的字节序列就不一样。所以在加密之前或加密之后需要将字符编码进行编码与解码。当然,这不是必须的,你可以使用系统默认的ASCII字符编码,只要统一即可。
数据加密后是以字节数组存在的,跟密钥类似,为了方面存储和传输,我们将加密后的结果转为Base64表示形式。
@@ -111,4 +111,4 @@ public void decrypt() throws InvalidKeyException, NoSuchAlgorithmException, NoSu
* 密码学:http://zh.wikipedia.org/wiki/%E5%AF%86%E7%A2%BC%E5%AD%B8
* 经典密码:http://zh.wikipedia.org/wiki/%E7%B6%93%E5%85%B8%E5%AF%86%E7%A2%BC
* DES:http://zh.wikipedia.org/wiki/%E8%B3%87%E6%96%99%E5%8A%A0%E5%AF%86%E6%A8%99%E6%BA%96
-* 3DES:http://zh.wikipedia.org/wiki/3DES
\ No newline at end of file
+* 3DES:http://zh.wikipedia.org/wiki/3DES
diff --git "a/28.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\351\235\236\345\257\271\347\247\260\345\212\240\345\257\206\347\256\227\346\263\225.md" "b/Java-Base/28.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\351\235\236\345\257\271\347\247\260\345\212\240\345\257\206\347\256\227\346\263\225.md"
similarity index 92%
rename from "28.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\351\235\236\345\257\271\347\247\260\345\212\240\345\257\206\347\256\227\346\263\225.md"
rename to "Java-Base/28.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\351\235\236\345\257\271\347\247\260\345\212\240\345\257\206\347\256\227\346\263\225.md"
index 025fe05..d55dda2 100644
--- "a/28.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\351\235\236\345\257\271\347\247\260\345\212\240\345\257\206\347\256\227\346\263\225.md"
+++ "b/Java-Base/28.Java\345\212\240\345\257\206\350\247\243\345\257\206\344\271\213\351\235\236\345\257\271\347\247\260\345\212\240\345\257\206\347\256\227\346\263\225.md"
@@ -1,4 +1,4 @@
-##28.1 非对称加密算法
+## 28.1 非对称加密算法
**非对称加密算法**与**对称加密算法**的区别在于:对称加密算法加密与解密使用的密钥是相同的,而非对称加密算法的加密与解密使用的密钥是不相同的,在这两个密钥中,一个公开,成为**公钥**,一个保密,成为**私钥**。
@@ -6,18 +6,18 @@

-##28.2 常用非对称加密算法
+## 28.2 常用非对称加密算法
-###28.2.1 典型非对称加密算法:RSA
+### 28.2.1 典型非对称加密算法:RSA
-RSA算法密钥的长度为512位至65535位之间,且必须是64的倍数。Java6默认的RSA算法的密钥长度是1014位。
+RSA算法密钥的长度为512位至65535位之间,且必须是64的倍数。Java6默认的RSA算法的密钥长度是1024位。
-###28.2.2 常用非对称加密算法:EIGamal
+### 28.2.2 常用非对称加密算法:EIGamal
EIGamal算法密钥的长度为160位至16384位之间,且必须为8的倍数。Java没有默认对EIGamal算法的实现。如果需要使用GIGmal算法,可以使用Bouncy Castle的实现。
-##28.3 代码示例
-###28.3.1 密钥生成
+## 28.3 代码示例
+### 28.3.1 密钥生成
```Java
@Test
@@ -33,7 +33,7 @@ public void t4_keyPair() throws NoSuchAlgorithmException {
}
```
-###28.3.2 加密
+### 28.3.2 加密
```Java
@Test
@@ -53,7 +53,7 @@ public void t5_encrypt() throws NoSuchAlgorithmException, NoSuchPaddingException
}
```
-###28.3.3 解密
+### 28.3.3 解密
```Java
@Test
@@ -74,4 +74,4 @@ public void t6_decrypt() throws NoSuchAlgorithmException, InvalidKeySpecExceptio
}
```
-##28.4 参考资料
\ No newline at end of file
+## 28.4 参考资料
diff --git "a/29.Java8\344\271\213Stream.md" "b/Java-Base/29.Java8\344\271\213Stream.md"
similarity index 100%
rename from "29.Java8\344\271\213Stream.md"
rename to "Java-Base/29.Java8\344\271\213Stream.md"
diff --git a/Java-Base/30.Java Runtime Data Areas.md b/Java-Base/30.Java Runtime Data Areas.md
new file mode 100644
index 0000000..ce8f7ab
--- /dev/null
+++ b/Java-Base/30.Java Runtime Data Areas.md
@@ -0,0 +1,76 @@
+# 30.Java Runtime Data Areas.md
+
+ +
+## 30.1 运行时数据区(Runtime Data Areas)
+
+Java虚拟机为程序的运行提供了各种不同的数据区,部分数据区与JVM的生命周期一致(随JVM启动而分配,JVM退出而释放),而另一部分则跟线程绑定,随着线程的启动和退出进行分配和释放。
+
+### 30.1.1 程序计数器(Program Counter Rigister)
+
+Java虚拟机支持多个线程在同一时刻运行。每一个Java虚拟机线程拥有自己的程序计数器。在任意时刻,任意线程都处于一个方法中(称为当前方法(current method)),如果是该方法是**非本地方法(not native method)**,则该程序计数器记录着**Java虚拟机执行的当前指令的地址**。而如果该方法为**本地方法(native method)**,则该程序计数器为undefined。
+
+### 30.1.2 Java虚拟机栈(Java Virtual Machine Stacks)
+
+每个Java虚拟机线程都拥有各自的**Java虚拟机栈**,并与线程同时被创建。Java虚拟机栈用于存储**帧(frames)**。Java虚拟机栈跟传统语言的栈相似:存储局部变量、结果,同时参与方法的调用和返回。
+Because the Java Virtual Machine stack is never manipulated directly except to push and pop frames, frames may be heap allocated. The memory for a Java Virtual Machine stack does not need to be contiguous.
+
+在第一版的Java虚拟机规范中,**Java虚拟机栈**做为**Java栈** 为人们所熟知。这个规范允许Java虚拟机栈是固定的大小或根据需要通过计算来动态地扩展和收缩。如果Java虚拟机堆的大小是固定的,(If the Java Virtual Machine stacks are of a fixed size, the size of each Java Virtual Machine stack may be chosen independently when that stack is created.)
+
+Java虚拟的实现可以提供让程序员或用户来控制Java虚拟栈初始大小,并且,可以让Java虚拟机栈在最小值和最大值的限制范围内根据实际需要动态地拓展或收缩。
+
+以下异常情况与Java虚拟栈相关:
+* 如果线程需要的Java虚拟机栈大小超过限额,则抛出**StackOverflowError**。
+* 如果Java虚拟机栈被设置为可动态拓展,当拓展时由于受限于物理内存的限制而无法实现拓展时,则抛出**OutOfMemoryError**。
+
+### 30.1.2 堆(Heap)
+
+Java虚拟机具有一个由所有Java虚拟机线程共享的一个堆。堆是**分配和储存所有的实例对象和数组的运行时数据区域**。
+
+堆是在Java虚拟机启动时被创建的。堆的对象储存空间通过**自动存储管理系统(garbage collector简称gc)**进行回收,并不能像c/c++语言那样显示地进行释放。Java虚拟机没有指定限制使用的gc,这个可以由程序员和用户根据自己的情况来进行选择。堆可以是固定大小的,也可以通过计算来动态地拓展和收缩。同时,堆的内容空间地址不需要是连续的。
+
+Java虚拟机的实现可以提供让程序员和用户控制初始的堆大小,并且,可以让栈在最小值和最大值的限制范围内根据实际需要动态地拓展或收缩。
+
+以下异常情况与堆相关:
+
+* 当堆需要拓展的内存大小大于自动存储管理系统所能提供的内存大小时,抛出**OutOfMemoryError**。
+
+### 方法区(Method Area)
+
+Java虚拟机拥有一个由所有Java虚拟机线程共享的方法区。方法区类似于传统语言的用于存储编译代码的内存区域。(The method area is analogous to the storage area for compiled code of a conventional language or analogous to the "text" segment in an operating system process. )它用于存储每个类的类结构,例如**运行时常量池(Runtime Constant Pool)**,字段和方法数据,以及方法和构造方法的代码,包括类、实例和接口在初始化时使用的特殊方法。
+
+方法区也是在Java虚拟机启动时创建的。虽然方法区作为堆的一部分,但简单的Java虚拟机的实现可能不会对这部分区域进行gc操作和内存紧凑操作。Java虚拟机规范并不强制规范方法区的存储位置和管理已编译代码的策略。方法区可以是固定大小,也可以根据实际需要对方法区的大小进行拓展和紧凑操作。同时,方法区的内存不需要是连续的。
+
+Java虚拟机的实现应该提供让程序员和用户控制初始的方法区内存大小,并且,可以让方法区在最小值和最大值的限制范围内根据实际需要动态地拓展或收缩。
+
+以下异常情况与方法区相关:
+* 如果方法区不能提供满足需要分配的内存时,Java虚拟机抛出**OutOfMemoryError**。
+
+###运行时常量池(Runtime Constant Pool)
+**运行时常量池**是一个类或接口的class文件的中**constant_pool**表的运行时表示。它包含多种常量:编译期的数值型字面量,运行时的方法和字段的引用。运行时常量池提供类似于一个传统的编程语言中的符号表的功能,但它比典型的符号表包含了更广泛的范围中的数据。
+
+每个运行时常量池都是在Java虚拟机的方法区中进行分配的(也就是说运行时常量池是方法区中的一部分)。类/接口的运行时常量池在类/接口创建时被Java虚拟机构造。
+
+以下异常情况与类/接口的运行时常量池的创建相关:
+
+当创建一个类或接口时,如果运行时常量池的创建需要更多的内存,而方法区没有足够的内存可以提供时,Java虚拟机抛出**OutOfMemoryError**。
+
+### 本地方法栈(Native Method Stacks)
+Java虚拟机应该使用传统的栈(通俗地将:C栈)来对**本地方法**(非Java实现的方法)进行支持。Native method stacks may also be used by the implementation of an interpreter for the Java Virtual Machine's instruction set in a language such as C. Java Virtual Machine implementations that cannot load native methods and that do not themselves rely on conventional stacks need not supply native method stacks. If supplied, native method stacks are typically allocated per thread when each thread is created.
+
+This specification permits native method stacks either to be of a fixed size or to dynamically expand and contract as required by the computation. If the native method stacks are of a fixed size, the size of each native method stack may be chosen independently when that stack is created.
+
+
+Java虚拟机的实现应当提供这样的功能:程序员和用户可以控制本地方法栈的初始化大小,并且,可以让本地方法栈在最小值和最大值的限制范围内根据实际需要动态地拓展或收缩。
+
+以下异常情况与本地方法栈相关:
+* 如果本地方法栈需要更多的内存,但无法进行分配时,Java虚拟机抛出**StackOverflowError**。
+
+
+If native method stacks can be dynamically expanded and native method stack expansion is attempted but insufficient memory can be made available, or if insufficient memory can be made available to create the initial native method stack for a new thread, the Java Virtual Machine throws an OutOfMemoryError.
+
+### 拓展阅读
+
+* 翻译自:http://docs.oracle.com/javase/specs/jvms/se8/html/jvms-2.html#jvms-2.5
+* understanding-jvm-internals: http://www.cubrid.org/blog/dev-platform/understanding-jvm-internals/
+* understanding-java-garbage-collection: http://www.cubrid.org/blog/dev-platform/understanding-java-garbage-collection/
diff --git a/Java-Base/31.Understanding Java Garbage Collection.md b/Java-Base/31.Understanding Java Garbage Collection.md
new file mode 100644
index 0000000..51beb95
--- /dev/null
+++ b/Java-Base/31.Understanding Java Garbage Collection.md
@@ -0,0 +1,120 @@
+#31.Understanding Java Garbage Collection
+
+理解GC(Garbage Collection)的工作原理对Java编程有什么益处呢?满足软件工程师的求知欲或许是一个不错的原因,但与此同时,也可以帮助你编写更加优秀的Java应用程序。
+
+这是我的个人的主观意见,但是我相信那些深谙GC的人往往更容易成为一个优秀的Java工程师。如果你对GC感兴趣,那么意味着你有不错的开发经验。如果你有过仔细选择合适的GC算法经验,这意味着你完全了解你开发应用程序的功能特点。当然,这也许只是优秀开发者的普遍衡量标准,然而我要说的是,要想成为一名优秀的开发者,理解GC是一门必修的课程。
+
+这篇文章的主要目的是以尽量简洁的方式向你讲解GC。我希望这篇文章能切切实实地对你有所帮助。回到正题,在GC中有个词汇**stop-the-word**,stop-the-word这个过程总会发生,无论你选择何种GC算法。stop-the-world意味着在**执行GC的过程中,JVM会中断所有的应用程序线程**( 除了GC需要的线程外)。被中断的线程会在GC完成后恢复。我们所关注的**GC调优就在于如何减少stop-the-world的运行时间**。
+
+## 垃圾收集器(Generational Garbage Collection)
+
+Java代码并不能显式地对内存进行分配和移除。有些人会将对象设置为null或者调用System.gc()方法来**显式**地移除内存空间。将对象设置为null没有大不了的,当调用System.gc()方法却会大大地响应系统的性能(我们并不需要这样做)。
+
+在Java中,开发者并不需要显式地在代码中释放内存,垃圾收集器会帮助我们找到不需要的对象并讲它们移除。垃圾收集器只所以被引入使用是基于以下两个假定前提:
+
+1. 大多数对象很快成为不可达状态;
+2. **老对象引用新对象**这种情况总是控制在很小的数量内。
+
+这两个假定前提被成为**弱世代假说(Weak generational hypothesis)**,基于这个假设,在HotSpot虚拟机中,内存(切确地说是Java Heap)被分为两种:**新生代(Young Generation)**与**老年代(Old Generation)**。
+
+新生代:绝大部分的新创建的对象都被分配到这里。由于大部分的对象很快会成为不可达状态,很多新创建的对象都分配到新生代,然后很快从这个区域被释放。对象从新生代被释放,我们称这个过程为**Minor GC**。
+
+老年代:当在新生代的对象没有成为不可达状态,并且从新生代存活下来后,我们会将这些对象复制到老年代。老年代的储存空间会比新生代的要大,所以在老年代发生GC的频率要远远低于在新生代的GC频率。对象从老年代被释放,我们称这个过程为**major GC**或**full GC**。
+
+我们看下以下两个图表:
+
+
 +
+以上图中**永久代(Permanent Generation)**被称为**方法区**,它用于存储class文件和运行时常量池。所以,这里的存储空间并不用于“收留”从老年代存活下来的对象。当GC可能会在这个区域发生,我们也把在这个区域发生的GC算作full GC。
+
+有些人会有疑问:当老年代的对象需要引用新生代的对象,这时候会发生什么情况?
+
+为了处理这些情况,在老年代中会有个叫做**卡表(card table)**的东西,它是一个512字节的数据块。在老年代的对象需要引用新生代的对象时,会被记录到这里。然后,当新生代的GC执行时,这个**card table**会被检查以确定对象是否应该被GC处理,这样做可以防止对老年代的所有对象进行遍历。这个卡表使用一个被称为**写屏障**的装置进行管理,它可以让minor GC的性能更加高效,虽然它本身也需要一定的开销,但是整体的开销却是减少的。
+
+
 +
+## 新生代(Composition of the Young Generation)
+
+为了深入理解GC,我们来看一下新生代。新生代被划分为3个区域空间:
+
+* 一个伊甸园(One Eden Space)
+* 两个幸存区 (Two Survivor Spaces)
+
+这三个区域空间中,有两个是幸存区(Survivor Spaces)。每个区域空间的执行过程如下:
+
+1. 绝大多数新创建的对象都首先被分配到伊甸园(Eden Space)。
+2. 当伊甸园的GC执行以后,存活下来的对象会被移动到其中一个幸存区(这个幸存区存放着之前存活下来的对象)。
+3. 一旦幸存区满了以后,该幸存区存活下来的对象会移动到另外一个幸存区,然后该幸存区会重置为空状态。
+4. 在多次幸存区的GC执行后而存活下来的对象会被移动到老年代。
+
+在这个过程中,其中一个幸存区必须要保持为空状态。如果两个幸存区都是空状态或者都同时存在数据,你的系统一定出现了什么错误。
+
+数据通过minor GC并堆砌进入老年代的过程如下图所示:
+
+
 +
+在HotSpot虚拟机中,有两项被用于快速分配内存的技术。一种被成为**bump-the-pointer**,而另一种是所谓的线程局部缓冲器TLABs (Thread-Local Allocation Buffers)。
+
+Bump-the-pointer technique tracks the last object allocated to the Eden space. That object will be located on top of the Eden space. And if there is an object created afterwards, it checks only if the size of the object is suitable for the Eden space. If the said object seems right, it will be placed in the Eden space, and the new object goes on top. So, when new objects are created, only the lastly added object needs to be checked, which allows much faster memory allocations. However, it is a different story if we consider a multithreaded environment. To save objects used by multiple threads in the Eden space for Thread-Safe, an inevitable lock will occur and the performance will drop due to the lock-contention. TLABs is the solution to this problem in HotSpot VM. This allows each thread to have a small portion of its Eden space that corresponds to its own share. As each thread can only access to their own TLAB, even the bump-the-pointer technique will allow memory allocations without a lock.
+
+你并不需要技术以上提到的两种技术。你需要记住的是:当对象创建之后会首先分配到伊甸园空间,然后通过在幸存区的长时间存活被晋升到老年代空间。
+
+##老年代的GC(GC for the Old Generation)
+
+老年代基本在空间被沾满时才执行GC操作。GC的执行过程根据GC的类型不同而有所差异,如果你对不同的GC类型有所了解,则会明白其中的差异所在。
+
+根据JDK7,共有5中GC类型:
+
+* Serial GC
+* Parallel GC
+* Parallel Old GC (Parrallel Compacting GC)
+* Concurrent Mark & Sweep GC (or CMS)
+* Garbage First GC (G1)
+
+其中,串行GC不能使用的操作的服务器上。这种类型的GC创建时有在台式计算机上只有一个CPU核心。使用该系列GC将显著删除应用程序的性能。 使用这种将很明显地降低应用程序的性能。
+
+现在让我们来了解每种GC的类型:
+
+###串行GC( Serial GC (-XX:+UseSerialGC))
+
+(The GC in the young generation uses the type we explained in the previous paragraph. ?)
+在新生代中我们使用一种称为**标记-清除-紧凑(mark-sweep-compact)**的算法。
+
+这种算法的第一步就是对新生代的幸存对象进行标记。然后,它从堆的从前往后逐个清理不需要的对象。最后对幸存的对象进行紧凑,使它们在位于连续的内存空间。这个过程会将堆分为两部分:一部分有数据,一部分没数据。Serial GC适用于小的内存空间和少量的CPU核心的机器。
+
+###并行GC (Parallel GC (-XX:+UseParallelGC))
+
+
 +
+ 看上图,你可以清楚看到Serial GC与Parallel之间的差异。Serial GC仅使用一个线程去执行GC过程,而Parallel GC会使用多个线程去执行GC过程,因此,可得到更加优秀的性能。当机器拥有很大的内存和较多的CPU核心时,Paraller GC会表现得非常不错。Parallel GC也被称为**throughput GC**。
+
+###Parallel Old GC
+
+Parallel Old GC从JDK 5 update版本开始得到支持。相比Parallel GC,唯一的区别在于:Parallel Old GC只工作于老年代。它通过三个步骤进行工作:标记-总结-紧凑。The summary step identifies the surviving objects separately for the areas that the GC have previously performed, and thus different from the sweep step of the mark-sweep-compact algorithm. It goes through a little more complicated steps.
+
+###Concurrent Mark & Sweep GC (or CMS)
+
+
 +
+ 如你上图所看的,Concurrent Mark-Sweep GC比之前介绍的几种GC都要复杂得多。早期的**初始标记阶**段很简单,它的主要功能是最接近根类加载器的对象进行标记,这个阶段的停顿时间十分短暂。在**并发标记**阶段,对刚刚幸存下来的对象的引用进行跟踪和检查,这个过程中,其他的JVM线程不会被中止(也就是没有stop-the-world)。在**重新标记**阶段,会对**并发标记**阶段新添加或停止的引用进行确认。最后,在**并发清除**阶段,对不可达对象进行清理工作(也就GC动作),这个过程,其他的JVM线程也不会被中止。由于这种GC工作方式,GC的停顿时间非常短暂。CMS GC也被称为**低延迟GC**,这对那些对响应时间有严格要求的应用程序是至关重要的。
+
+虽然这种GC垃圾收集的停顿时间非常短暂,但是他对内存大小和CPU内核数量与性能有着更高的要求。
+虽然这种GC类型具有极其短暂的停顿时间,但它也有以下缺点:
+
+* 对内存和CPU的要求更加高。
+* 不提供默认的内存紧凑步骤
+
+在使用这种GC之前,你需要仔细地review。此外,在内存紧凑阶段,如果存在大量的内存碎片,那么这种GC需要停顿时间可能会比其他的GC类型的要长。你需要仔细检查内存紧凑发生的频率和时间。
+
+###Garbage First GC (G1)
+
+最后,让我们来看下Garbage First GC(G1)
+
+
 +
+如果你想要了解G1 GC,首先你要忘记关于新生代和老年代的一切知识点。Java堆(新生代&老年代)被划分为一个个大小固定的区域,对象被分派到这些区域中,如果一个区域被占满,则继续分配另外的区域,同时在后台维护一个优先列表,每次在允许的GC时间内,优先回收占用内存多的对象,这是就G1的来源。
+
+待续...
+
+## 参考文档
+* 翻译自:http://www.cubrid.org/blog/dev-platform/understanding-java-garbage-collection/
diff --git "a/Java-Base/32.\350\277\255\344\273\243\345\231\250\346\250\241\345\274\217.md" "b/Java-Base/32.\350\277\255\344\273\243\345\231\250\346\250\241\345\274\217.md"
new file mode 100644
index 0000000..2238327
--- /dev/null
+++ "b/Java-Base/32.\350\277\255\344\273\243\345\231\250\346\250\241\345\274\217.md"
@@ -0,0 +1,69 @@
+# 32.迭代器模式
+
+## 32.1 从Iterable接口说起
+
+ 在Java中的集合类接口有Set、List、Map、Queue,而这些接口的子类不计其数。以List接口为例,常用的实现类有:ArrayList、LinkedList、Stack、Vector。每个List子类实现的方式各不一样,ArrayList使用数组,LinkedList使用链表,Stack和Vector可以数组,甚至有些其他的集合类使用混合的数据结构。
+
+ 为了对外隐藏集合类的实现方式,保持良好的封装性,必须要统一这些集合类的迭代接口。同时调用者也无效关心集合类的底层实现方式,使用统一的接口即可对集合进行迭代。
+
+ 这不禁让人想到Java的`Iterable`接口,这也是迭代器模式在JDK中的经典实例。
+
+## 32.2 ArrayList实现Iterable接口
+
+Iterable.java 实现:
+```Java
+public interface Iterable {
+ Iterator iterator();
+}
+```
+Iterator.java 实现
+```Java
+public interface Iterator {
+ boolean hasNext();
+ E next();
+}
+```
+ArrayList.java 实现 Iterable接口
+```Java
+ @Override
+ public Iterator iterator() {
+ return new ArrayListIterator();
+ }
+```
+
+ArrayListIterator.java 实现
+```Java
+public class ArrayListIterator {
+ int cursor;
+ int lastRet = -1;
+
+ public boolean hasNext() {
+ return cursor != size;
+ }
+
+ public E next() {
+ int i = cursor;
+ if (i >= size)
+ throw new NoSuchElementException();
+ Object[] elementData = ArrayList.this.elementData;
+ cursor = i + 1;
+ return (E) elementData[lastRet = i];
+ }
+}
+```
+
+为了减少类文件和易于维护,我们通常把ArrayListIterator.java作为ArrayList的内部类,或者在ArrayList的iterator方法中世界采用匿名内部类,这里我们使用的外部类。
+
+## 32.3 迭代器模式
+
+**意图**:使用统一的方式遍历集合的各个元素,而无需暴露集合的内部结构。
+
+**使用场景**:
+
+* 为聚合类统一遍历接口;
+* 需要为聚合类提供多种遍历方式,例如二叉树的前序遍历,中序遍历,后续遍历,层次遍历;
+* 访问聚合对象的内容而无需暴露其内部结构;
+
+**类图**:
+
+
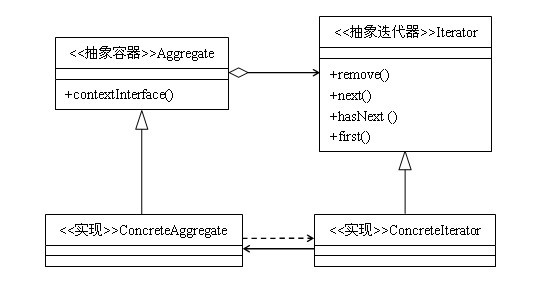 diff --git "a/Java-Base/33.\350\243\205\351\245\260\345\231\250\346\250\241\345\274\2172.md" "b/Java-Base/33.\350\243\205\351\245\260\345\231\250\346\250\241\345\274\2172.md"
new file mode 100644
index 0000000..fd930a4
--- /dev/null
+++ "b/Java-Base/33.\350\243\205\351\245\260\345\231\250\346\250\241\345\274\2172.md"
@@ -0,0 +1 @@
+# 33.装饰器模式2
diff --git "a/Java-Base/34.Java\344\270\255\347\232\204\345\274\272\350\275\257\345\274\261\350\231\232\345\274\225\347\224\250\345\217\212\345\205\266\345\272\224\347\224\250.md" "b/Java-Base/34.Java\344\270\255\347\232\204\345\274\272\350\275\257\345\274\261\350\231\232\345\274\225\347\224\250\345\217\212\345\205\266\345\272\224\347\224\250.md"
new file mode 100644
index 0000000..cf15502
--- /dev/null
+++ "b/Java-Base/34.Java\344\270\255\347\232\204\345\274\272\350\275\257\345\274\261\350\231\232\345\274\225\347\224\250\345\217\212\345\205\266\345\272\224\347\224\250.md"
@@ -0,0 +1,50 @@
+# 34.Java中的强软弱虚引用及其应用
+
+## 34.1 强引用(Strong References)
+
+强引用是使用最频繁的引用。例如:
+```Java
+Object obj = new Object();
+```
+如果一个对象有强引用,则垃圾回收器不会回收它。即使JVM内存不足,也是抛出`OutOfMemeoryError`来停止程序,也不会通过回收强引用来释放内存。
+
+##34.2 软引用(Soft Reference)
+
+如果一个对象只有软引用,则在JVM足够时该对象不会被回收,而当JVM不足时就会回收该对象释放内存。
+
+```Java
+SoftReference