diff --git a/Data/iris.csv b/Data/iris.csv
new file mode 100644
index 0000000..973902e
--- /dev/null
+++ b/Data/iris.csv
@@ -0,0 +1,149 @@
+sepallength,sepalwidth,petallength,petalwidth,class
+4.7,3.2,1.3,0.2,1
+4.6,3.1,1.5,0.2,1
+5.0,3.6,1.4,0.2,1
+5.4,3.9,1.7,0.4,1
+4.6,3.4,1.4,0.3,1
+5.0,3.4,1.5,0.2,1
+4.4,2.9,1.4,0.2,1
+4.9,3.1,1.5,0.1,1
+5.4,3.7,1.5,0.2,1
+4.8,3.4,1.6,0.2,1
+4.8,3.0,1.4,0.1,1
+4.3,3.0,1.1,0.1,1
+5.8,4.0,1.2,0.2,1
+5.7,4.4,1.5,0.4,1
+5.4,3.9,1.3,0.4,1
+5.1,3.5,1.4,0.3,1
+5.7,3.8,1.7,0.3,1
+5.1,3.8,1.5,0.3,1
+5.4,3.4,1.7,0.2,1
+5.1,3.7,1.5,0.4,1
+4.6,3.6,1.0,0.2,1
+5.1,3.3,1.7,0.5,1
+4.8,3.4,1.9,0.2,1
+5.0,3.0,1.6,0.2,1
+5.0,3.4,1.6,0.4,1
+5.2,3.5,1.5,0.2,1
+5.2,3.4,1.4,0.2,1
+4.7,3.2,1.6,0.2,1
+4.8,3.1,1.6,0.2,1
+5.4,3.4,1.5,0.4,1
+5.2,4.1,1.5,0.1,1
+5.5,4.2,1.4,0.2,1
+4.9,3.1,1.5,0.1,1
+5.0,3.2,1.2,0.2,1
+5.5,3.5,1.3,0.2,1
+4.9,3.1,1.5,0.1,1
+4.4,3.0,1.3,0.2,1
+5.1,3.4,1.5,0.2,1
+5.0,3.5,1.3,0.3,1
+4.5,2.3,1.3,0.3,1
+4.4,3.2,1.3,0.2,1
+5.0,3.5,1.6,0.6,1
+5.1,3.8,1.9,0.4,1
+4.8,3.0,1.4,0.3,1
+5.1,3.8,1.6,0.2,1
+4.6,3.2,1.4,0.2,1
+5.3,3.7,1.5,0.2,1
+5.0,3.3,1.4,0.2,1
+7.0,3.2,4.7,1.4,2
+6.4,3.2,4.5,1.5,2
+6.9,3.1,4.9,1.5,2
+5.5,2.3,4.0,1.3,2
+6.5,2.8,4.6,1.5,2
+5.7,2.8,4.5,1.3,2
+6.3,3.3,4.7,1.6,2
+4.9,2.4,3.3,1.0,2
+6.6,2.9,4.6,1.3,2
+5.2,2.7,3.9,1.4,2
+5.0,2.0,3.5,1.0,2
+5.9,3.0,4.2,1.5,2
+6.0,2.2,4.0,1.0,2
+6.1,2.9,4.7,1.4,2
+5.6,2.9,3.6,1.3,2
+6.7,3.1,4.4,1.4,2
+5.6,3.0,4.5,1.5,2
+5.8,2.7,4.1,1.0,2
+6.2,2.2,4.5,1.5,2
+5.6,2.5,3.9,1.1,2
+5.9,3.2,4.8,1.8,2
+6.1,2.8,4.0,1.3,2
+6.3,2.5,4.9,1.5,2
+6.1,2.8,4.7,1.2,2
+6.4,2.9,4.3,1.3,2
+6.6,3.0,4.4,1.4,2
+6.8,2.8,4.8,1.4,2
+6.7,3.0,5.0,1.7,2
+6.0,2.9,4.5,1.5,2
+5.7,2.6,3.5,1.0,2
+5.5,2.4,3.8,1.1,2
+5.5,2.4,3.7,1.0,2
+5.8,2.7,3.9,1.2,2
+6.0,2.7,5.1,1.6,2
+5.4,3.0,4.5,1.5,2
+6.0,3.4,4.5,1.6,2
+6.7,3.1,4.7,1.5,2
+6.3,2.3,4.4,1.3,2
+5.6,3.0,4.1,1.3,2
+5.5,2.5,4.0,1.3,2
+5.5,2.6,4.4,1.2,2
+6.1,3.0,4.6,1.4,2
+5.8,2.6,4.0,1.2,2
+5.0,2.3,3.3,1.0,2
+5.6,2.7,4.2,1.3,2
+5.7,3.0,4.2,1.2,2
+5.7,2.9,4.2,1.3,2
+6.2,2.9,4.3,1.3,2
+5.1,2.5,3.0,1.1,2
+5.7,2.8,4.1,1.3,2
+6.3,3.3,6.0,2.5,3
+5.8,2.7,5.1,1.9,3
+7.1,3.0,5.9,2.1,3
+6.3,2.9,5.6,1.8,3
+6.5,3.0,5.8,2.2,3
+7.6,3.0,6.6,2.1,3
+4.9,2.5,4.5,1.7,3
+7.3,2.9,6.3,1.8,3
+6.7,2.5,5.8,1.8,3
+7.2,3.6,6.1,2.5,3
+6.5,3.2,5.1,2.0,3
+6.4,2.7,5.3,1.9,3
+6.8,3.0,5.5,2.1,3
+5.7,2.5,5.0,2.0,3
+5.8,2.8,5.1,2.4,3
+6.4,3.2,5.3,2.3,3
+6.5,3.0,5.5,1.8,3
+7.7,3.8,6.7,2.2,3
+7.7,2.6,6.9,2.3,3
+6.0,2.2,5.0,1.5,3
+6.9,3.2,5.7,2.3,3
+5.6,2.8,4.9,2.0,3
+7.7,2.8,6.7,2.0,3
+6.3,2.7,4.9,1.8,3
+6.7,3.3,5.7,2.1,3
+7.2,3.2,6.0,1.8,3
+6.2,2.8,4.8,1.8,3
+6.1,3.0,4.9,1.8,3
+6.4,2.8,5.6,2.1,3
+7.2,3.0,5.8,1.6,3
+7.4,2.8,6.1,1.9,3
+7.9,3.8,6.4,2.0,3
+6.4,2.8,5.6,2.2,3
+6.3,2.8,5.1,1.5,3
+6.1,2.6,5.6,1.4,3
+7.7,3.0,6.1,2.3,3
+6.3,3.4,5.6,2.4,3
+6.4,3.1,5.5,1.8,3
+6.0,3.0,4.8,1.8,3
+6.9,3.1,5.4,2.1,3
+6.7,3.1,5.6,2.4,3
+6.9,3.1,5.1,2.3,3
+5.8,2.7,5.1,1.9,3
+6.8,3.2,5.9,2.3,3
+6.7,3.3,5.7,2.5,3
+6.7,3.0,5.2,2.3,3
+6.3,2.5,5.0,1.9,3
+6.5,3.0,5.2,2.0,3
+6.2,3.4,5.4,2.3,3
+5.9,3.0,5.1,1.8,3
\ No newline at end of file
diff --git a/Data/santander.zip b/Data/santander.zip
new file mode 100644
index 0000000..b35e9f4
Binary files /dev/null and b/Data/santander.zip differ
diff --git a/FeatureSelection-RemovingConstant_QuasiConstant_DuplicateFeatures.ipynb b/FeatureSelection-RemovingConstant_QuasiConstant_DuplicateFeatures.ipynb
new file mode 100644
index 0000000..dcc7bf6
--- /dev/null
+++ b/FeatureSelection-RemovingConstant_QuasiConstant_DuplicateFeatures.ipynb
@@ -0,0 +1,1275 @@
+{
+ "cells": [
+ {
+ "cell_type": "code",
+ "execution_count": 1,
+ "metadata": {},
+ "outputs": [
+ {
+ "name": "stderr",
+ "output_type": "stream",
+ "text": [
+ "C:\\Users\\Lenovo\\Anaconda3\\lib\\site-packages\\sklearn\\cross_validation.py:41: DeprecationWarning: This module was deprecated in version 0.18 in favor of the model_selection module into which all the refactored classes and functions are moved. Also note that the interface of the new CV iterators are different from that of this module. This module will be removed in 0.20.\n",
+ " \"This module will be removed in 0.20.\", DeprecationWarning)\n"
+ ]
+ }
+ ],
+ "source": [
+ "import numpy as np\n",
+ "import pandas as pd\n",
+ "import seaborn as sns\n",
+ "import matplotlib.pyplot as plt\n",
+ "\n",
+ "from sklearn.ensemble import RandomForestClassifier\n",
+ "from sklearn.cross_validation import train_test_split\n",
+ "from sklearn.metrics import accuracy_score\n",
+ "from sklearn.model_selection import cross_val_score\n",
+ "\n",
+ "from sklearn.feature_selection import VarianceThreshold"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 2,
+ "metadata": {},
+ "outputs": [
+ {
+ "data": {
+ "text/html": [
+ "\n",
+ "\n",
+ "
\n",
+ " \n",
+ " \n",
+ " | \n",
+ " ID | \n",
+ " var3 | \n",
+ " var15 | \n",
+ " imp_ent_var16_ult1 | \n",
+ " imp_op_var39_comer_ult1 | \n",
+ " imp_op_var39_comer_ult3 | \n",
+ " imp_op_var40_comer_ult1 | \n",
+ " imp_op_var40_comer_ult3 | \n",
+ " imp_op_var40_efect_ult1 | \n",
+ " imp_op_var40_efect_ult3 | \n",
+ " ... | \n",
+ " saldo_medio_var33_hace2 | \n",
+ " saldo_medio_var33_hace3 | \n",
+ " saldo_medio_var33_ult1 | \n",
+ " saldo_medio_var33_ult3 | \n",
+ " saldo_medio_var44_hace2 | \n",
+ " saldo_medio_var44_hace3 | \n",
+ " saldo_medio_var44_ult1 | \n",
+ " saldo_medio_var44_ult3 | \n",
+ " var38 | \n",
+ " TARGET | \n",
+ "
\n",
+ " \n",
+ " \n",
+ " \n",
+ " | 0 | \n",
+ " 1 | \n",
+ " 2 | \n",
+ " 23 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0 | \n",
+ " 0 | \n",
+ " ... | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 39205.170000 | \n",
+ " 0 | \n",
+ "
\n",
+ " \n",
+ " | 1 | \n",
+ " 3 | \n",
+ " 2 | \n",
+ " 34 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0 | \n",
+ " 0 | \n",
+ " ... | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 49278.030000 | \n",
+ " 0 | \n",
+ "
\n",
+ " \n",
+ " | 2 | \n",
+ " 4 | \n",
+ " 2 | \n",
+ " 23 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0 | \n",
+ " 0 | \n",
+ " ... | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 67333.770000 | \n",
+ " 0 | \n",
+ "
\n",
+ " \n",
+ " | 3 | \n",
+ " 8 | \n",
+ " 2 | \n",
+ " 37 | \n",
+ " 0.0 | \n",
+ " 195.0 | \n",
+ " 195.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0 | \n",
+ " 0 | \n",
+ " ... | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 64007.970000 | \n",
+ " 0 | \n",
+ "
\n",
+ " \n",
+ " | 4 | \n",
+ " 10 | \n",
+ " 2 | \n",
+ " 39 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0 | \n",
+ " 0 | \n",
+ " ... | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 0.0 | \n",
+ " 117310.979016 | \n",
+ " 0 | \n",
+ "
\n",
+ " \n",
+ "
\n",
+ "
5 rows × 371 columns
\n",
+ "
\n",
+ "\n",
+ "
\n",
+ " \n",
+ " \n",
+ " | \n",
+ " 0 | \n",
+ "
\n",
+ " \n",
+ " \n",
+ " \n",
+ " | TARGET | \n",
+ " 0 | \n",
+ "
\n",
+ " \n",
+ " | num_op_var41_ult1 | \n",
+ " 0 | \n",
+ "
\n",
+ " \n",
+ " | num_var26 | \n",
+ " 0 | \n",
+ "
\n",
+ " \n",
+ " | num_var25_0 | \n",
+ " 0 | \n",
+ "
\n",
+ " \n",
+ " | num_var25 | \n",
+ " 0 | \n",
+ "
\n",
+ " \n",
+ "
\n",
+ "
[START] CHEKING CONSTANT COLUMNS
"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 13,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "## To know those 79 constant features/columns. We will use \"Boolean Column Selection\" method:\n",
+ "## list=[True,False.....] # Here length of list = Total number of columns\n",
+ "## dataframe[list]\n",
+ "## Now this dataframe will contain only those columns for which the corresponding order in the list is True!\n",
+ "## To apply it here - Convert the 79 False values to 79 True values."
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 14,
+ "metadata": {},
+ "outputs": [
+ {
+ "data": {
+ "text/plain": [
+ "[False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " True,\n",
+ " True,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " True,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False,\n",
+ " False]"
+ ]
+ },
+ "execution_count": 14,
+ "metadata": {},
+ "output_type": "execute_result"
+ }
+ ],
+ "source": [
+ "constantFeatues = [ not tmp for tmp in constant_filter.get_support()]\n",
+ "constantFeatues"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 15,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "## From the above result: True=79 | False=291 "
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 16,
+ "metadata": {},
+ "outputs": [
+ {
+ "data": {
+ "text/plain": [
+ "Index(['ind_var2_0', 'ind_var2', 'ind_var13_medio_0', 'ind_var13_medio',\n",
+ " 'ind_var18_0', 'ind_var18', 'ind_var27_0', 'ind_var28_0', 'ind_var28',\n",
+ " 'ind_var27', 'ind_var34_0', 'ind_var34', 'ind_var41', 'ind_var46_0',\n",
+ " 'ind_var46', 'num_var13_medio_0', 'num_var13_medio', 'num_var18_0',\n",
+ " 'num_var18', 'num_var27_0', 'num_var28_0', 'num_var28', 'num_var27',\n",
+ " 'num_var34_0', 'num_var34', 'num_var41', 'num_var46_0', 'num_var46',\n",
+ " 'saldo_var13_medio', 'saldo_var18', 'saldo_var28', 'saldo_var27',\n",
+ " 'saldo_var34', 'saldo_var41', 'saldo_var46',\n",
+ " 'delta_imp_amort_var18_1y3', 'delta_imp_amort_var34_1y3',\n",
+ " 'delta_imp_reemb_var33_1y3', 'delta_imp_trasp_var17_out_1y3',\n",
+ " 'delta_imp_trasp_var33_out_1y3', 'delta_num_reemb_var33_1y3',\n",
+ " 'delta_num_trasp_var17_out_1y3', 'delta_num_trasp_var33_out_1y3',\n",
+ " 'imp_amort_var18_hace3', 'imp_amort_var18_ult1',\n",
+ " 'imp_amort_var34_hace3', 'imp_amort_var34_ult1', 'imp_var7_emit_ult1',\n",
+ " 'imp_reemb_var13_hace3', 'imp_reemb_var17_hace3',\n",
+ " 'imp_reemb_var33_hace3', 'imp_reemb_var33_ult1',\n",
+ " 'imp_trasp_var17_in_hace3', 'imp_trasp_var17_out_hace3',\n",
+ " 'imp_trasp_var17_out_ult1', 'imp_trasp_var33_in_hace3',\n",
+ " 'imp_trasp_var33_out_hace3', 'imp_trasp_var33_out_ult1',\n",
+ " 'ind_var7_emit_ult1', 'num_var2_0_ult1', 'num_var2_ult1',\n",
+ " 'num_var7_emit_ult1', 'num_meses_var13_medio_ult3',\n",
+ " 'num_reemb_var13_hace3', 'num_reemb_var17_hace3',\n",
+ " 'num_reemb_var33_hace3', 'num_reemb_var33_ult1',\n",
+ " 'num_trasp_var17_in_hace3', 'num_trasp_var17_out_hace3',\n",
+ " 'num_trasp_var17_out_ult1', 'num_trasp_var33_in_hace3',\n",
+ " 'num_trasp_var33_out_hace3', 'num_trasp_var33_out_ult1',\n",
+ " 'saldo_var2_ult1', 'saldo_medio_var13_medio_hace2',\n",
+ " 'saldo_medio_var13_medio_hace3', 'saldo_medio_var13_medio_ult1',\n",
+ " 'saldo_medio_var13_medio_ult3', 'saldo_medio_var29_hace3'],\n",
+ " dtype='object')"
+ ]
+ },
+ "execution_count": 16,
+ "metadata": {},
+ "output_type": "execute_result"
+ }
+ ],
+ "source": [
+ "all_X.columns[constantFeatues]"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 17,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "## Conclusion: The above columns are constants !!"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {},
+ "source": [
+ "[END] CHEKING CONSTANT COLUMNS
"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 18,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "X_train_filter = constant_filter.transform(train_X)\n",
+ "X_test_filter = constant_filter.transform(test_X)"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 19,
+ "metadata": {},
+ "outputs": [
+ {
+ "name": "stdout",
+ "output_type": "stream",
+ "text": [
+ "(16000, 291)\n",
+ "(4000, 291)\n"
+ ]
+ }
+ ],
+ "source": [
+ "print(X_train_filter.shape)\n",
+ "print(X_test_filter.shape)"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {},
+ "source": [
+ "### Removing Quasi-Constant /Almost constant - same values for a very large subsets:"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 20,
+ "metadata": {},
+ "outputs": [
+ {
+ "data": {
+ "text/plain": [
+ "VarianceThreshold(threshold=0.01)"
+ ]
+ },
+ "execution_count": 20,
+ "metadata": {},
+ "output_type": "execute_result"
+ }
+ ],
+ "source": [
+ "quasi_constant_filter = VarianceThreshold(threshold=0.01)\n",
+ "quasi_constant_filter.fit(X_train_filter)"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 21,
+ "metadata": {},
+ "outputs": [
+ {
+ "name": "stdout",
+ "output_type": "stream",
+ "text": [
+ "291\n",
+ "245\n"
+ ]
+ }
+ ],
+ "source": [
+ "print(len(quasi_constant_filter.get_support()))\n",
+ "print(quasi_constant_filter.get_support().sum())"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 22,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "## Earlier 291, now 245. There are 46 Quasi constant features."
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 23,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "X_train_filter_quasi = quasi_constant_filter.transform(X_train_filter)\n",
+ "X_test_filter_quasi = quasi_constant_filter.transform(X_test_filter)"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 24,
+ "metadata": {},
+ "outputs": [
+ {
+ "name": "stdout",
+ "output_type": "stream",
+ "text": [
+ "(16000, 245)\n",
+ "(4000, 245)\n"
+ ]
+ }
+ ],
+ "source": [
+ "print(X_train_filter_quasi.shape)\n",
+ "print(X_test_filter_quasi.shape)"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {},
+ "source": [
+ "### Removing Duplicate features:"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 25,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "X_train_filter_quasi_T = X_train_filter_quasi.T\n",
+ "X_test_filter_quasi_T = X_test_filter_quasi.T"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 26,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "X_train_filter_quasi_T = pd.DataFrame(X_train_filter_quasi_T)\n",
+ "X_test_filter_quasi_T = pd.DataFrame(X_test_filter_quasi_T)"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 27,
+ "metadata": {},
+ "outputs": [
+ {
+ "name": "stdout",
+ "output_type": "stream",
+ "text": [
+ "(245, 16000)\n",
+ "(245, 4000)\n"
+ ]
+ }
+ ],
+ "source": [
+ "print(X_train_filter_quasi_T.shape)\n",
+ "print(X_test_filter_quasi_T.shape)"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "print(X_train_filter_quasi_T.duplicated().sum())\n",
+ "print(X_test_filter_quasi_T.duplicated().sum())"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "duplicatedTrainFeatures = X_train_filter_quasi_T.duplicated()\n",
+ "duplicatedTestFeatures = X_test_filter_quasi_T.duplicated()"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "featuresToKeep = [not index for index in duplicatedTrainFeatures]\n"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "X_train_unique = X_train_filter_quasi_T[featuresToKeep].T\n",
+ "X_test_unique = X_test_filter_quasi_T[featuresToKeep].T"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "print(X_train_unique.shape)\n",
+ "print(X_test_unique.shape)"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": []
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": []
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": []
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": []
+ }
+ ],
+ "metadata": {
+ "kernelspec": {
+ "display_name": "Python 3",
+ "language": "python",
+ "name": "python3"
+ },
+ "language_info": {
+ "codemirror_mode": {
+ "name": "ipython",
+ "version": 3
+ },
+ "file_extension": ".py",
+ "mimetype": "text/x-python",
+ "name": "python",
+ "nbconvert_exporter": "python",
+ "pygments_lexer": "ipython3",
+ "version": "3.6.4"
+ }
+ },
+ "nbformat": 4,
+ "nbformat_minor": 2
+}
diff --git a/FeatureSelection.ipynb b/FeatureSelection.ipynb
new file mode 100644
index 0000000..f3ad56f
--- /dev/null
+++ b/FeatureSelection.ipynb
@@ -0,0 +1,635 @@
+{
+ "cells": [
+ {
+ "cell_type": "markdown",
+ "metadata": {},
+ "source": [
+ "Feature Selection: It is the process of selecting the most important/relevant features of a dataset.\n",
+ "\n",
+ "\n",
+ " - It enables the machine learning algorithm to train faster.\n",
+ " - It reduces the complexity of a model and makes it easier to interpret.\n",
+ " - It improves the accuracy of a model if the right subset is chosen.\n",
+ " - It reduces Overfitting."
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 62,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "import pandas as pd\n",
+ "import numpy as np"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 64,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "data = pd.read_csv('C://Users//Lenovo//Documents//Desktop//IPY//iris.csv')"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 65,
+ "metadata": {},
+ "outputs": [
+ {
+ "data": {
+ "text/html": [
+ "\n",
+ "\n",
+ "
\n",
+ " \n",
+ " \n",
+ " | \n",
+ " sepallength | \n",
+ " sepalwidth | \n",
+ " petallength | \n",
+ " petalwidth | \n",
+ " class | \n",
+ "
\n",
+ " \n",
+ " \n",
+ " \n",
+ " | 0 | \n",
+ " 4.7 | \n",
+ " 3.2 | \n",
+ " 1.3 | \n",
+ " 0.2 | \n",
+ " 1 | \n",
+ "
\n",
+ " \n",
+ " | 1 | \n",
+ " 4.6 | \n",
+ " 3.1 | \n",
+ " 1.5 | \n",
+ " 0.2 | \n",
+ " 1 | \n",
+ "
\n",
+ " \n",
+ " | 2 | \n",
+ " 5.0 | \n",
+ " 3.6 | \n",
+ " 1.4 | \n",
+ " 0.2 | \n",
+ " 1 | \n",
+ "
\n",
+ " \n",
+ " | 3 | \n",
+ " 5.4 | \n",
+ " 3.9 | \n",
+ " 1.7 | \n",
+ " 0.4 | \n",
+ " 1 | \n",
+ "
\n",
+ " \n",
+ " | 4 | \n",
+ " 4.6 | \n",
+ " 3.4 | \n",
+ " 1.4 | \n",
+ " 0.3 | \n",
+ " 1 | \n",
+ "
\n",
+ " \n",
+ "
\n",
+ "
\n",
+ "[2] This approach will not work when feature sets contain different units (e.g., one feature is in years while a another feature is in dollars)"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {},
+ "source": [
+ "# WAY#2: Thresholding on Missing Values"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 81,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "#half_count = len(df) / 2\n",
+ "#df = df.dropna(thresh=half_count,axis=1) # Drop any column with more than 50% missing values"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {},
+ "source": [
+ "# WAY#3: Thresholding on Binary Feature Variance\n"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 82,
+ "metadata": {},
+ "outputs": [
+ {
+ "data": {
+ "text/plain": [
+ "array([[0],\n",
+ " [1],\n",
+ " [0],\n",
+ " [1],\n",
+ " [0]], dtype=int64)"
+ ]
+ },
+ "execution_count": 82,
+ "metadata": {},
+ "output_type": "execute_result"
+ }
+ ],
+ "source": [
+ "# Create feature Dataframe with:\n",
+ "# Feature 0: 80% class 0\n",
+ "# Feature 1: 80% class 1\n",
+ "# Feature 2: 60% class 0, 40% class 1\n",
+ "dummyData = {'col1': [0,0,0,0,1], 'col2': [1,1,1,1,0], 'col3':[0,1,0,1,0]}\n",
+ "dummyDataFrame = pd.DataFrame(data=dummyData)\n",
+ "\n",
+ "# Run threshold by -Bernoulli Random Variable Variance\n",
+ "thresholder = VarianceThreshold(threshold=(.75 * (1 - .75)))\n",
+ "thresholder.fit_transform(dummyDataFrame)"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {},
+ "source": [
+ "# WAY#4: Feature Selection from Highly Correlated Features\n",
+ "\n",
+ "#### If two features are highly correlated, then the information they contain is very similar, and it is likely redundant to include both features. Therefore, we remove one of them from the feature set."
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 83,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "# Create feature Dataframe with two highly correlated features\n",
+ "dummyData = {'col1': [1,2,3,4,5,6,7,8,9], 'col2': [1,2,3,4,5,6,7,7,7], 'col3':[1,0,1,0,1,0,1,0,1]}\n",
+ "\n",
+ "# Convert feature matrix into DataFrame\n",
+ "dataframe = pd.DataFrame(dummyData)\n",
+ "\n",
+ "# Create correlation matrix\n",
+ "corr_matrix = dataframe.corr().abs()"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": 84,
+ "metadata": {},
+ "outputs": [
+ {
+ "data": {
+ "text/html": [
+ "\n",
+ "\n",
+ "
\n",
+ " \n",
+ " \n",
+ " | \n",
+ " col1 | \n",
+ " col2 | \n",
+ " col3 | \n",
+ "
\n",
+ " \n",
+ " \n",
+ " \n",
+ " | col1 | \n",
+ " 1.000000 | \n",
+ " 0.976103 | \n",
+ " 0.000000 | \n",
+ "
\n",
+ " \n",
+ " | col2 | \n",
+ " 0.976103 | \n",
+ " 1.000000 | \n",
+ " 0.034503 | \n",
+ "
\n",
+ " \n",
+ " | col3 | \n",
+ " 0.000000 | \n",
+ " 0.034503 | \n",
+ " 1.000000 | \n",
+ "
\n",
+ " \n",
+ "
\n",
+ "
\n",
+ "\n",
+ "
\n",
+ " \n",
+ " \n",
+ " | \n",
+ " col1 | \n",
+ " col3 | \n",
+ "
\n",
+ " \n",
+ " \n",
+ " \n",
+ " | 0 | \n",
+ " 1 | \n",
+ " 1 | \n",
+ "
\n",
+ " \n",
+ " | 1 | \n",
+ " 2 | \n",
+ " 0 | \n",
+ "
\n",
+ " \n",
+ " | 2 | \n",
+ " 3 | \n",
+ " 1 | \n",
+ "
\n",
+ " \n",
+ "
\n",
+ "
-
-
-- ###### [Analysis on Titanic Dataset](https://github.com/rahulvaish/MachineLearning-Python/tree/Titanic)
- ###### This example is analysis on Titanic Dataset. [[source Code]](https://github.com/rahulvaish/MachineLearning-Python/tree/Titanic)
- * Load the data[titanic.csv]
- * Clean and Prepare Data
- * Create Sparse Matrix
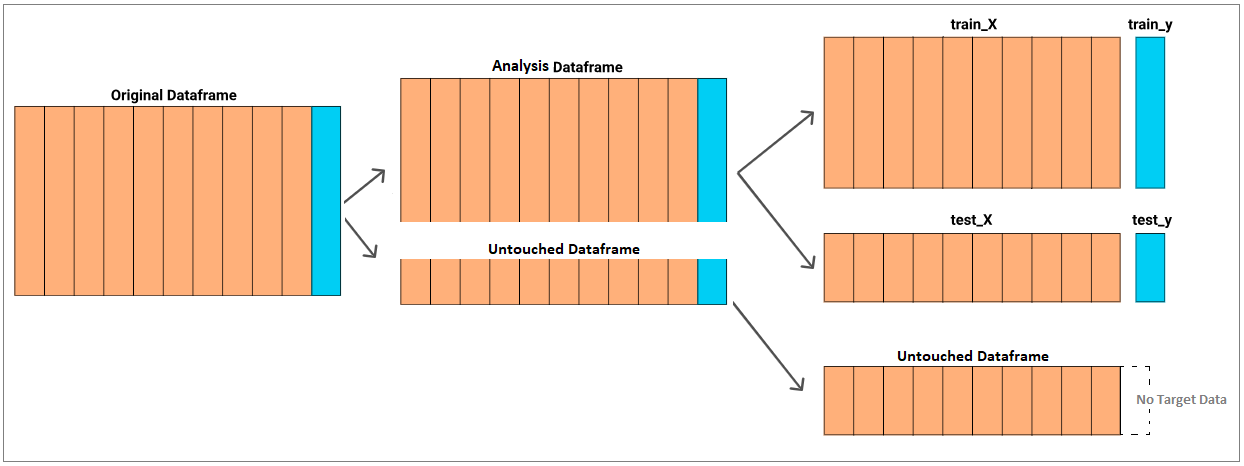
- * Split Dataframe as (Train+Test)+(Untouched - Target)
- **Pictorial Representation:**
- 
- * Apply ML Model
- * Make Prediction
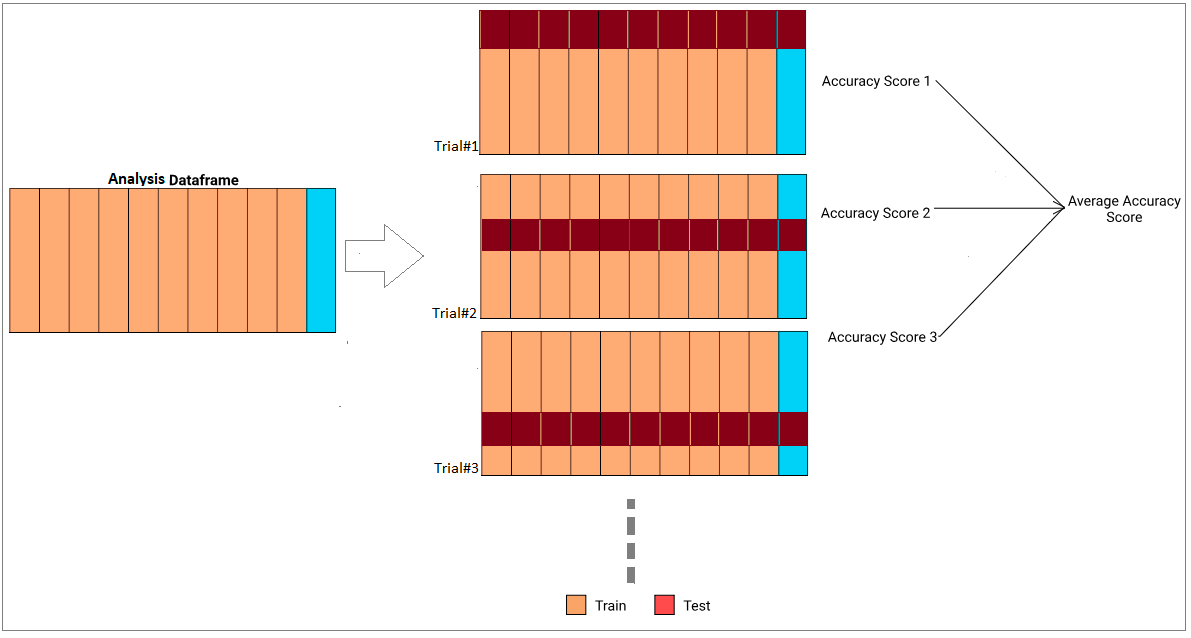
- * Cross Validate
- 
- * Make Predictions
-
-
-- ###### [Analysis on IRIS Dataset](https://github.com/rahulvaish/MachineLearning-Python/tree/IRIS)
- ###### This example is analysis on IRIS Dataset. [[source Code]](https://github.com/rahulvaish/MachineLearning-Python/tree/IRIS)
- * Load the data[iris.csv]
- * Clean and Prepare Data
- * Split Dataframe as (Train+Test)+(Untouched - Target)
- **Refer [above](#analysis-on-titanic-dataset) for Pictorial representation**
- * Apply ML Model
- * Make Prediction
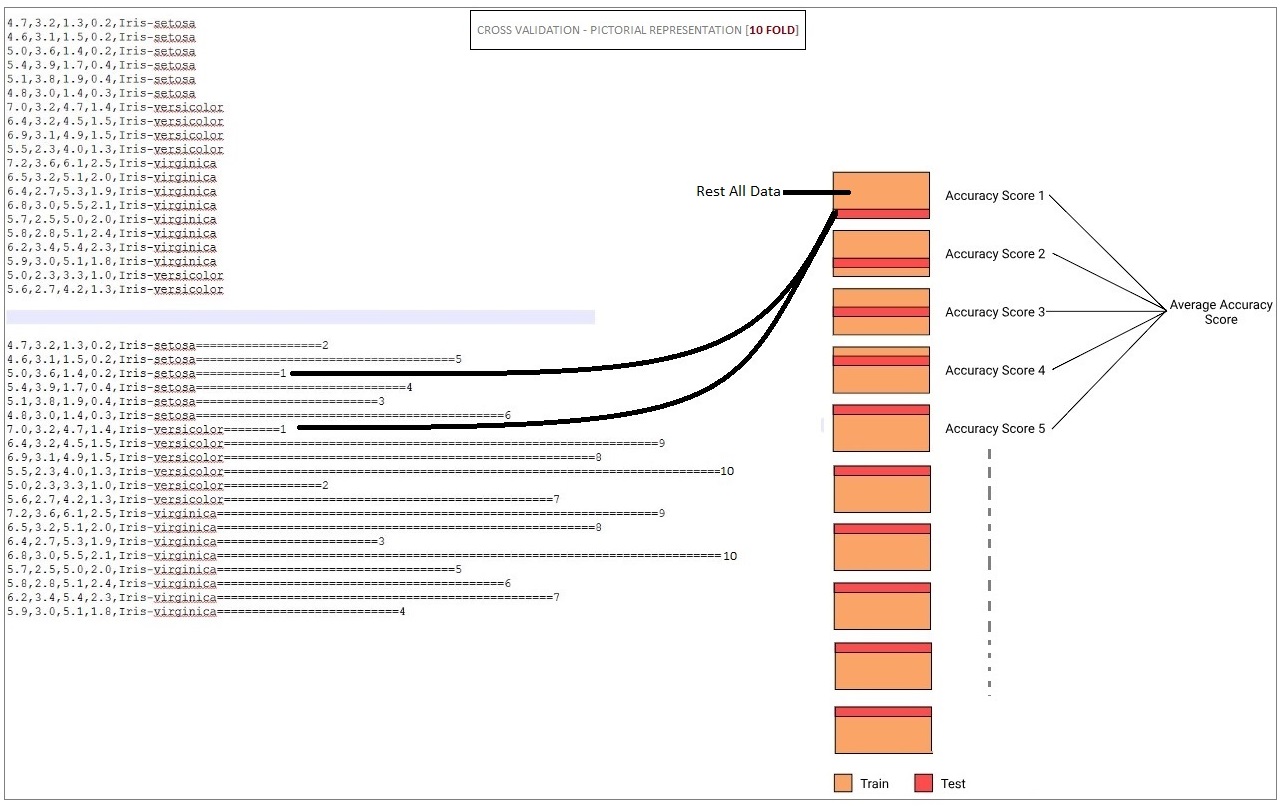
- * Cross Validate
-
- * Make Predictions
-
-
-
-- ###### [Analysis on House Price Dataset](https://github.com/rahulvaish/MachineLearning-Python/tree/HousePriceCompetition)
- ###### This example is analysis on House Price Dataset.[[Source Code]](https://github.com/rahulvaish/MachineLearning-Python/tree/HousePriceCompetition)
- * Load the data[HousePricingTutorial.csv]
- * Normalize
- * Analyse Correlation
- * Clean and Prepare Data
- * Split Dataframe as (Train+Test)+(Untouched - Target)
- **Refer [above](#analysis-on-titanic-dataset) for Pictorial representation**
- * Apply ML Model
- * Make Prediction
- * Cross Validate
- **Refer [above](#analysis-on-titanic-dataset) for Pictorial representation**
- * Make Predictions
-
-
-- ###### [Data Cleaning](https://github.com/rahulvaish/MachineLearning-Python/tree/DataWrangling/DataCleaning)
- ###### This example explains various methods of cleaning Data. [[Source Code]](https://github.com/rahulvaish/MachineLearning-Python/tree/DataWrangling/DataCleaning)
- * Load the data[Loan.csv]
- * Column selection in Dataframe
- * Dropping off Useless Columns
- * Dropping off Rows (on condition)
- * Type Conversion
- * Converting Non-Numerical Columns into Numerical Columns/Sparse
- * Determining Null Values
- * Filtering Data on Threshold Benchmark
- * Handling Missing Values
- * Queries on Dataframe
- * Split Dataframe Column Values[Example: Date]
- * Data Replacment-Unary|Binary|Sparse
-
-
-
-
-- ###### [Data Consolidation](https://github.com/rahulvaish/MachineLearning-Python/tree/DataWrangling/DataConsolidation)
- ###### This example explains various methods of consolidating Data. [[Source Code]](https://github.com/rahulvaish/MachineLearning-Python/tree/DataWrangling/DataConsolidation)
- * Concatinating Dataframe
- * Appending Dataframe
- * Joining Dataframe
- * Merging Dataframe
-
-
-
-
-- ###### [MySQL and Pandas](https://github.com/rahulvaish/MachineLearning-Python/tree/DataWrangling/MySQL%2BPandas)
- ###### This example explains the connectivity between MySQL and Pandas. [[Source Code]](https://github.com/rahulvaish/MachineLearning-Python/tree/DataWrangling/MySQL%2BPandas)
-
-
-
-- ###### [Pivot Tables](https://github.com/rahulvaish/MachineLearning-Python/tree/DataWrangling/PivotTables)
- ###### This example explains the concept of Pivot Tables and GroupBy. [[Source Code]](https://github.com/rahulvaish/MachineLearning-Python/tree/DataWrangling/PivotTables)
- * Load the data[schools_with_btoilet.csv/schools_with_gtoilet.csv]
- * Apply Panda's Pivot Method
- 
-
-
-
-
-
-- ###### [Data Visualization](https://github.com/rahulvaish/MachineLearning-Python/tree/DataVisualization)
- ###### This branch contains example which explains how to Visualize data in various forms of Graphs. [[Source Code]](https://github.com/rahulvaish/MachineLearning-Python/tree/DataVisualization)
-
- * Pair Plot
- * Line Graph
- * Histo Graph
- * Bar Plot
- * Scatter Plots
- * Box Plots
- * Heat Maps
-
-
-
-